pdf-redactor
pdf-redactor is a free, open-source Python tool for changing PDF text layers and metadata on Linux or on-premises systems.
What pdf-redactor is
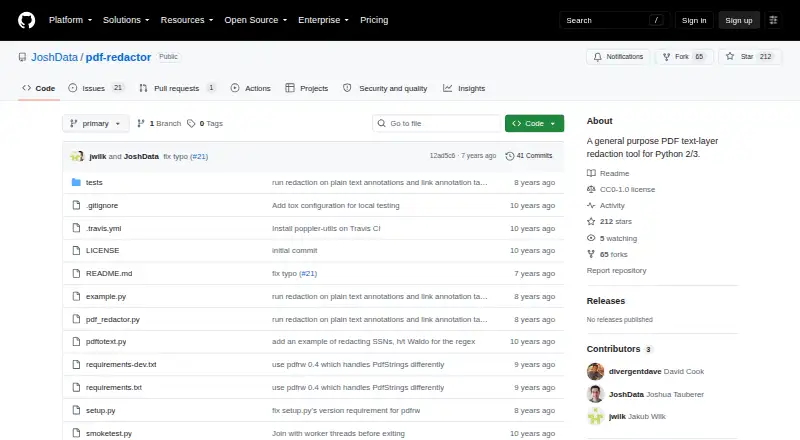
pdf-redactor is a free, open-source Python tool for changing PDF text layers and metadata on Linux or on-premises systems. It processes page text, plain-text annotations, link target URLs, the Document Information Dictionary, and embedded XMP metadata. Regular-expression filters can substitute text, such as replacing sensitive number patterns with a chosen mask. Metadata fields and XML metadata can be rewritten, removed, or added. The project uses pdfrw to parse and write PDFs and recommends qpdf for decompressing and recompressing content streams. Its documentation favors using the Python module with user-written text filters; the command-line version does not yet modify PDFs by itself. The repository carries a CC0 1.0 Universal license and credits Joshua Tauberer and Antoine McGrath. Graphical elements, images, and other embedded resources remain untouched. It does not inspect embedded files, multimedia, scripts, forms, internal object names, rich-text annotations, or digital signatures. Unusual fonts may disrupt matching or replacement rendering, and OCR redaction is not provided.
Good
- Free CC0 open-source project
- Supports regular-expression text substitution
- Edits document and XMP metadata
- Works as a Python library
- On-premises deployment
Watch out
- Command-line tool does not modify PDFs
- Images and graphics are untouched
- No OCR redaction
- Many PDF components are not inspected
Who it suits
It suits Python users who need on-premises redaction of PDF text layers, links, or metadata through custom filters. It is not intended for image-based or broad visual-content redaction.
Verdict
pdf-redactor provides focused, programmable text and metadata redaction rather than complete PDF sanitization. Its library-first workflow and coverage limits make careful scope checking necessary.
The facts
Each one read from pdf-redactor's own pages, with the date it was checked.
What it does
- Authors
- The README credits Joshua Tauberer and Antoine McGrath.checked 9 Oct 2026
- Command-line status
- The README says the command-line version does not yet actually do anything to the PDF.checked 9 Oct 2026
- Compression guidance
- The README recommends using qpdf to decompress PDFs before processing and to recompress and linearize them afterward because pdfrw does not support all content-stream compression methods.checked 9 Oct 2026
- Compression limit
- Because pdfrw does not support all content-stream compression methods, the README recommends decompressing PDFs with qpdf before processing them.checked 4 Oct 2026
- Content it handles
- It can process page text, plain-text annotations, link target URLs, document information metadata, and embedded XMP metadata.checked 4 Oct 2026
- Content not touched
- Graphical elements, images, and other embedded resources are not touched.checked 9 Oct 2026
- Coverage limits
- The README says it does not inspect some PDF components, including embedded files, multimedia, scripts, forms, internal object names, and digital signatures.checked 4 Oct 2026
- Font limit
- Unusual fonts may not be processed correctly, which can prevent text patterns from matching or replacement text from rendering correctly.checked 4 Oct 2026
- Font limitation
- Unusual fonts may not be processed correctly because the tool has limited understanding of glyph-to-Unicode mappings.checked 9 Oct 2026
- Implementation dependency
- The project uses pdfrw to parse and write PDFs.checked 9 Oct 2026
- Integration
- The project uses pdfrw to parse and write PDFs, and recommends qpdf to decompress and recompress PDFs when needed.checked 4 Oct 2026
- License
- The repository displays a CC0-1.0 license.checked 9 Oct 2026
- Metadata
- It can rewrite, remove, or add document metadata fields and XML metadata.checked 4 Oct 2026
- Metadata editing
- It can rewrite, remove, or add metadata fields and XML metadata through functions operating on the parsed XMP DOM.checked 9 Oct 2026
- Partial coverage
- The README lists embedded files, multimedia, scripts, rich-text annotations, forms, internal object names, and digital signatures among PDF content it does not scan.checked 9 Oct 2026
- Purpose
- pdf-redactor is a general-purpose PDF text-layer redaction tool written in pure Python.checked 9 Oct 2026
- Python library
- The README recommends using pdf_redactor as a library with Python text-filtering functions; it also documents Python 3 installation and a Python 3 command-line invocation.checked 9 Oct 2026
- Redaction targets
- It can process page text, plain text annotations, link target URLs, the Document Information Dictionary, and embedded XMP metadata.checked 9 Oct 2026
- Text redaction
- It supports regular-expression text substitution, such as replacing Social Security numbers with a mask.checked 4 Oct 2026
- Text substitution
- It supports regular-expression text substitution, such as replacing Social Security numbers with a chosen string.checked 9 Oct 2026
- Use
- The README recommends using the Python module as a library with user-written text filters; the command-line version does not yet do anything to the PDF by itself.checked 4 Oct 2026
- Visual content
- Graphical elements, images, and other embedded resources are not touched.checked 4 Oct 2026
The company
- Maker
- The README credits Joshua Tauberer and Antoine McGrath as the authors.checked 4 Oct 2026
Alternatives to pdf-redactor
- 1
GroupDocs.Redaction
AndroidiOSWebAPI7.6$1,999 usage-based - 2
Redactable
Free planWebAPI7.4From $19 a month - 3
RedactLaw
Free planWebAPISelf-hosted7.4From $39 a month - 4
Docuflair Redact
AndroidiOSWebLinux7.2From €3,588 a year - 5
BleachPDF
Free planOpen sourceLinuxmacOSSelf-hosted7.0Free plan - 6
Excise
Free planAPILinuxmacOSWindows6.8Free plan