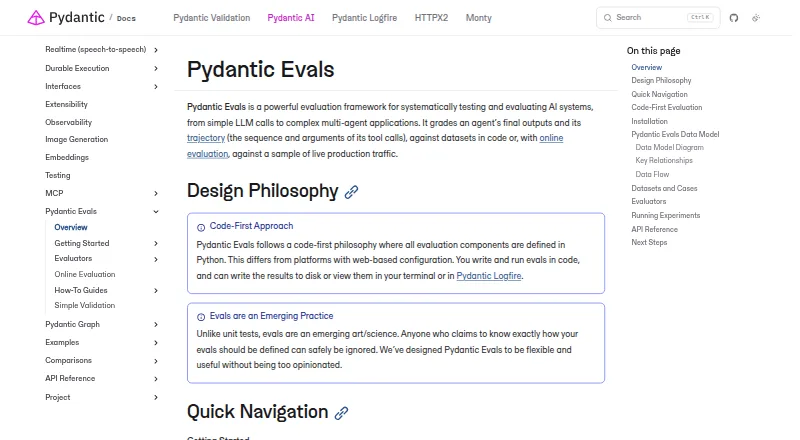
Pydantic Evals
Score6.4
Rank#16 of 30
Free planNo
Runs onLinux
Summary
Pydantic Evals is ranked #16 of 30 in AI LLM evaluation tools on Everything Xiaomi. It runs on Linux.
Compared on AI LLM evaluation tools
- Free plan
- Yespydantic.dev
- Evaluation methods
- Deterministic checks; custom evaluators; LLM judges; G-Eval; performance checks; report evaluators; span-based evaluation; agentic trajectory evaluationpydantic.dev
- Model support
- OpenAI; Anthropic; Gemini; xAI; Bedrock; Cerebras; Cohere; Groq; Hugging Face; Mistral; OpenRouter; and other listed Pydantic AI providerspydantic.dev
- Safety evaluations
- Yespydantic.dev
- Deployment
- self-hostedpydantic.dev
- Prompt versioning
- Yespydantic.dev
- API access
- Yespydantic.dev
Facts
- Purpose
- Pydantic Evals is a Python evaluation framework for testing AI systems, from individual LLM calls to multi-agent applications.pydantic.dev · 29 Sept 2026
- What it evaluates
- It grades agents’ final outputs and tool-call trajectories against datasets or sampled live production traffic.pydantic.dev · 29 Sept 2026
- Code-first workflow
- Evaluation components are defined in Python or loaded as serialized data, and experiment reports can be printed, stored, serialized, or sent to other applications.pydantic.dev · 29 Sept 2026
- Evaluators
- It includes built-in deterministic evaluators and supports custom evaluators, LLM judges, and evaluators that return assertions, scores, or labels.pydantic.dev · 29 Sept 2026
- Agent behavior checks
- Built-in evaluator examples cover tool correctness, trajectory matching, argument correctness, maximum tool calls, and maximum model requests.pydantic.dev · 29 Sept 2026
- Production evaluation
- Online evaluation can attach evaluators to production or staging traffic so every call or a sampled subset is graded in the background.pydantic.dev · 29 Sept 2026
- Logfire integration
- With the optional Logfire dependency, evaluation results can be sent to Logfire for visualization, comparison, and collaborative analysis, and OpenTelemetry traces can be used in evaluations.pydantic.dev · 29 Sept 2026
- Third-party integrations
- The documentation shows adapters for Ragas and DeepEval; these are optional dependencies and are not installed with pydantic-evals.pydantic.dev · 29 Sept 2026
- Installation
- The package is installed with pip or uv using the pydantic-evals package name.pydantic.dev · 29 Sept 2026
- Dependencies
- Pydantic Evals does not depend on pydantic-ai, and Logfire is optional.pydantic.dev · 29 Sept 2026
- Cost consideration
- LLM-as-a-judge evaluations can take seconds, cost money, and produce non-deterministic results; deterministic evaluators are described as having no cost.pydantic.dev · 29 Sept 2026
- Security
- Pydantic’s Logfire security page states that it has SOC 2 Type 2 audited controls, GDPR compliance, and HIPAA support under a signed Business Associate Agreement.pydantic.dev · 29 Sept 2026
- Maker
- Pydantic’s About page identifies the maker as Pydantic and describes its mission, but the opened page did not provide a headquarters or founding date.pydantic.dev · 29 Sept 2026
- Datasets and cases
- Datasets group test cases, which can include inputs, expected outputs, metadata, and case-specific evaluators.pydantic.dev · 30 Sept 2026
- Evaluator types
- Evaluators include deterministic checks, LLM judges, span-based and agentic evaluators, and custom evaluators.pydantic.dev · 30 Sept 2026
- Online evaluation
- Evaluators can run in the background on every production or staging call, or on a sampled subset of traffic.pydantic.dev · 30 Sept 2026
- Costs and tradeoffs
- LLM judges can be slower, cost money, be non-deterministic, and have biases.pydantic.dev · 30 Sept 2026
- Related service security
- Pydantic says Logfire is SOC 2 Type 2 audited, GDPR aligned, and can support HIPAA workloads under a signed Business Associate Agreement.pydantic.dev · 30 Sept 2026
Best Pydantic Evals alternatives
See all 12
Where it ranks on Everything Xiaomi
- Best AI LLM Evaluation Tools in 2026#16 of 30
Is Pydantic Evals yours?
Claim it for free: prove the domain, then correct facts, plans and screenshots. An editor reviews every change.
Sources
- pydantic.dev/docs/ai/evals/evals/· checked 29 Sept 2026
- pydantic.dev/docs/ai/evals/evaluators/overview/· checked 29 Sept 2026
- pydantic.dev/docs/ai/evals/evaluators/framework-inte· checked 29 Sept 2026
- pydantic.dev/security· checked 29 Sept 2026
- pydantic.dev/about· checked 29 Sept 2026