Marquez
Marquez collects, stores, and visualizes OpenLineage metadata from data jobs and applications.
What Marquez is
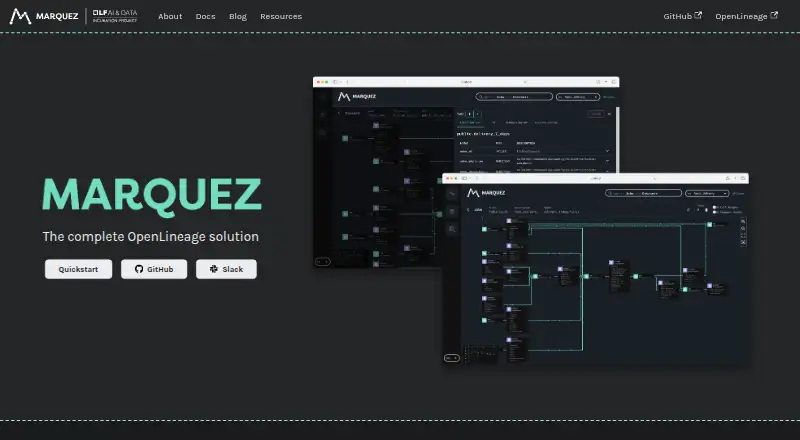
Marquez collects, stores, and visualizes OpenLineage metadata from data jobs and applications. Its metadata server offers a compatible endpoint for real-time collection, and its web interface maps dependencies so teams can inspect job inputs and outputs, dataset lineage, performance metrics, and execution details. The Lineage API supports dependency queries and traversal for work such as backfills and root cause analysis. Marquez also keeps metadata versions, dataset changes, and job-run history, which can help with audits and investigating downstream effects of schema changes. Integrations available through the OpenLineage community include Apache Airflow, Apache Spark, Apache Flink, dbt, and Dagster. The project describes an architecture with a metadata repository, REST API, and UI, and deployment guidance covers Docker and Kubernetes with PostgreSQL for metadata storage. Marquez is free and open source. Its API has no authentication or authorization enabled by default, and column lineage support is limited to the Spark integration.
Good
- Collects OpenLineage metadata in real time.
- Visualizes dataset lineage and job dependencies.
- Tracks dataset changes and job-run history.
- Supports integrations including Airflow, Spark, and dbt.
Watch out
- API authentication and authorization are off by default.
- Column lineage is limited to the Spark integration.
Who it suits
Marquez suits data teams that need to track metadata and lineage across processing applications and pipelines. It may also fit teams investigating dependencies, schema changes, or job performance.
Verdict
Marquez brings metadata collection, lineage views, and history together for data teams. Consider its default API security configuration and Spark-only column lineage support when evaluating it.
The facts
Each one read from Marquez's own pages, with the date it was checked.
What it does
- Architecture
- The documented system includes a metadata repository, RESTful metadata API, and metadata UI.checked 11 Oct 2026
- Audience
- Marquez is designed for data teams managing metadata and lineage across data processing applications and pipelines.checked 11 Oct 2026
- Authentication
- Clients can send an API key using Bearer Auth when configured, while the Marquez HTTP API does not require authentication or authorization by default.checked 11 Oct 2026
- Column lineage limit
- The site says column lineage support is limited to the Spark integration.checked 11 Oct 2026
- Deployment
- The deployment guide describes Docker and Kubernetes deployments and says the HTTP API server uses PostgreSQL to store dataset, job, and run metadata.checked 11 Oct 2026
- Getting started
- The quickstart documents MacOS/Linux and Windows prerequisites and runs the Marquez HTTP server using Docker.checked 11 Oct 2026
- Integrations
- The site names Apache Airflow, Apache Spark, Apache Flink, dbt, and Dagster as integrations supported through the OpenLineage community.checked 11 Oct 2026
- Lineage API
- The Lineage API supports dependency traversal and metadata queries for tasks such as backfills and root cause analysis.checked 11 Oct 2026
- Lineage visualization
- The web UI maps dependencies across a data ecosystem and lets users inspect job inputs and outputs, dataset lineage, performance metrics, and execution details.checked 11 Oct 2026
- Metadata collection
- Its metadata server provides an OpenLineage-compatible endpoint for real-time collection from running jobs and applications.checked 11 Oct 2026
- Metadata history
- Marquez records job run history, job statistics, and immutable versioned dataset metadata.checked 11 Oct 2026
- Open source
- The site says Marquez was released and open sourced by WeWork.checked 11 Oct 2026
- Purpose
- Marquez consumes, stores, and visualizes OpenLineage metadata for use cases including data governance, data quality monitoring, and performance analytics.checked 11 Oct 2026
- Real-time collection
- Its metadata server provides an OpenLineage-compatible endpoint to collect information from running jobs and applications.checked 11 Oct 2026
- Security limitation
- The deployment documentation states that authentication and authorization are not enabled on the API by default.checked 11 Oct 2026
- Support
- The site directs users to its Slack channel for help and feedback and encourages newcomers to join monthly community meetings.checked 11 Oct 2026
- Visual lineage
- The web UI maps dependencies in a data ecosystem and lets users inspect job inputs and outputs, dataset lineage, performance metrics, and execution details.checked 11 Oct 2026
Alternatives to Marquez
- 1
Atlas
Free planOpen sourceWebAPILinuxmacOS8.3From $39 a month - 2
Coalesce Catalog
Free planWebAPIExtension7.5From $150 a month - 3
Microsoft Defender for Business
AndroidiOSAPImacOS7.5 - 4

Apache Atlas
Free planOpen sourceWebAPILinuxSelf-hosted7.2Free plan - 57.0From $1.15 a month
- 6

Dataedo
WebExtensionSelf-hostedWindows6.5From $18,000 a year