HAMi
HAMi is open-source GPU virtualization middleware for sharing and scheduling heterogeneous accelerators across AI workloads on Kubernetes.
What HAMi is
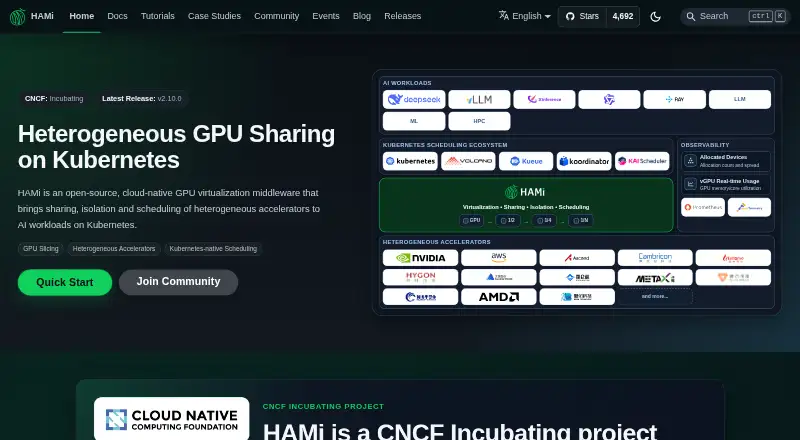
HAMi is open-source GPU virtualization middleware for sharing and scheduling heterogeneous accelerators across AI workloads on Kubernetes. Workloads can request GPU memory and core limits through Kubernetes resource limits, while scheduling options include binpack, spread and numa-first. The project lists support for accelerators from NVIDIA, AMD, AWS Neuron, Huawei Ascend, Cambricon and other vendors, though isolation and partitioning capabilities vary by device. HAMi works with Kubernetes APIs, DRA and CDI, and documents scheduling integrations with Volcano, Kueue, Koordinator and NVIDIA KAI Scheduler. A node metrics endpoint exposes device memory and core utilization for Prometheus. Classic HAMi needs Kubernetes v1.23 or later; HAMi-DRA needs v1.34 or later plus its stated feature gate, CDI and NVIDIA driver 440 or later. NVIDIA limit enforcement uses user-space library interception, so it does not cover applications that bypass CUDA. The FAQ describes memory and compute enforcement as soft and best-effort, recommending MIG where hardware-enforced isolation is required. HAMi is free and self-hosted.
Good
- Free, open-source middleware for Kubernetes.
- GPU memory and core quotas are supported.
- Scheduling offers binpack, spread and numa-first.
- Metrics expose device memory and core utilization.
- Documentation covers multiple accelerator vendors.
Watch out
- NVIDIA controls do not cover applications bypassing CUDA.
- Memory and compute enforcement is soft and best-effort.
- Some devices lack isolation or multi-card partitioning.
- HAMi-DRA requires Kubernetes v1.34 or later.
Who it suits
HAMi suits teams running AI, machine-learning or HPC workloads on Kubernetes that need to share accelerators and manage GPU quotas. It is also relevant to operators who want device utilization metrics and scheduling integrations.
Verdict
HAMi offers Kubernetes-based accelerator sharing, quota controls and scheduling across a broad device list. Check device-specific isolation support and the stated Kubernetes requirements before choosing it for workloads with strict isolation needs.
Plans and prices
From HAMi's own pricing page, checked 4 Oct 2026.
| Plan | Price | What it gives you |
|---|---|---|
| HAMi | Free | Open-source GPU virtualization middleware for AI workloads on Kubernetes |
The facts
Each one read from HAMi's own pages, with the date it was checked.
What it does
- Accelerators
- The project lists support for NVIDIA, AWS Neuron, Huawei Ascend, Cambricon, Enflame, Hygon, Iluvatar, Kunlunxin, MetaX, Moore Threads, Vastai, AMD and Biren accelerators.checked 3 Oct 2026
- Community support
- The project links to community support through Discord and Slack (#hami-dev).checked 4 Oct 2026
- Deployment
- The quick start installs HAMi with Helm and requires Kubernetes, Helm, kubectl, and installation permissions.checked 4 Oct 2026
- Deployment requirements
- Classic HAMi supports Kubernetes v1.23 or later; HAMi-DRA requires Kubernetes v1.34 or later with the DRA Consumable Capacity feature gate enabled, CDI and NVIDIA driver 440 or later.checked 3 Oct 2026
- Ecosystem integrations
- The project documents integrations with Volcano, Kueue, Koordinator, and NVIDIA KAI Scheduler.checked 4 Oct 2026
- Integrations
- The site lists Kubernetes, Volcano, Kueue, Koordinator and KAI Scheduler in its Kubernetes scheduling ecosystem.checked 3 Oct 2026
- Isolation limits
- The FAQ characterizes HAMi vGPU memory and compute enforcement as soft and best-effort, and recommends MIG when hardware-enforced isolation is required for compliance or SLAs.checked 3 Oct 2026
- Isolation mechanism
- For NVIDIA devices, HAMi enforces limits through user-space library interception; the FAQ says applications that bypass the CUDA library are not covered.checked 3 Oct 2026
- Kubernetes integration
- HAMi works with Kubernetes APIs, DRA, and CDI.checked 4 Oct 2026
- Limitations
- The supported-device matrix marks memory isolation, core isolation, and multi-card partitioning as unavailable for some listed devices.checked 4 Oct 2026
- Monitoring
- HAMi provides allocation counts and spread plus real-time GPU memory and core utilization visibility.checked 4 Oct 2026
- Product
- HAMi is open-source GPU virtualization middleware that enables sharing, isolation and scheduling of heterogeneous accelerators for AI workloads on Kubernetes.checked 3 Oct 2026
- Project status
- HAMi is a CNCF Incubating project.checked 4 Oct 2026
- Purpose
- HAMi is open-source, cloud-native GPU virtualization middleware for sharing, isolating, and scheduling heterogeneous accelerators on Kubernetes.checked 4 Oct 2026
- Resource controls
- HAMi supports GPU memory and compute quotas, with hard runtime isolation for supported devices.checked 4 Oct 2026
- Resource slicing
- HAMi lets workloads request GPU memory and core limits using Kubernetes resource limits such as `nvidia.com/gpumem` and `nvidia.com/gpucores`.checked 3 Oct 2026
- Scheduling
- HAMi offers binpack, spread, and topology-aware scheduling policies.checked 4 Oct 2026
- Scheduling limit
- HAMi's built-in priority field supports two levels; the FAQ recommends integrating Volcano for multi-level queue priorities.checked 3 Oct 2026
- Support
- The site links to documentation, tutorials, Discord and the `#hami-dev` Slack channel for community resources.checked 3 Oct 2026
- Workloads
- The site identifies LLM, machine-learning, and HPC workloads as use cases.checked 4 Oct 2026
Where it runs
- Device coverage
- The v2.10.0 supported-device matrix lists NVIDIA, Cambricon, Hygon, Huawei Ascend, Iluvatar, Mthreads, MetaX, Enflame, Kunlunxin, Vastai, AMD, AWS Neuron, and Biren devices as stable.checked 4 Oct 2026
The full review of HAMi
HAMi is open-source middleware for dividing accelerator capacity among Kubernetes workloads. It is best suited to teams running self-hosted AI, machine-learning or HPC clusters with mixed GPU hardware and multiple tenants. The strongest case is flexible sharing at no license cost; the crucial caveat is that isolation is not universally hard-enforced.
Overview
HAMi turns accelerator capacity into Kubernetes-managed resources rather than requiring every job to reserve an entire device. Workloads can request GPU memory and compute limits with resources such as nvidia.com/gpumem and nvidia.com/gpucores, allowing operators to place more jobs on shared hardware while retaining quota controls.
Its placement policies are binpack, spread and numa-first. Binpack is useful when you want to concentrate workloads and leave other devices free; spread favors distributing jobs; numa-first can help placement decisions that depend on NUMA locality. Binpack and spread can be selected at either node or GPU scope.
The supported-device list spans NVIDIA, AMD, AWS Neuron, Huawei Ascend, Cambricon, Enflame, Hygon, Iluvatar, Kunlunxin, MetaX, Moore Threads, Vastai and Biren accelerators. That breadth makes HAMi a credible choice for heterogeneous clusters, but capabilities vary by device. The support matrix marks memory isolation, core isolation or multi-card partitioning unavailable for some models.
Key features
Quotas, placement and monitoring
GPU memory and compute quotas give platform teams a practical way to constrain individual workloads. HAMi also exposes real-time device memory and core utilization at a node metrics endpoint that Prometheus can scrape, which is useful for capacity planning and operational alerts.
HAMi connects with Kubernetes APIs, DRA and CDI, and documents integrations with Volcano, Kueue, Koordinator and NVIDIA KAI Scheduler. Its built-in priority field has only two levels; clusters needing richer queue hierarchies should use Volcano for multi-level priorities.
Isolation and deployment
For NVIDIA devices, limits are enforced by intercepting user-space libraries. Applications that bypass the CUDA library are outside that protection. The project describes vGPU memory and compute enforcement as soft and best-effort, so teams with compliance obligations or SLA-grade separation should prefer hardware-enforced MIG where supported.
Classic HAMi requires Kubernetes 1.23 or later. HAMi-DRA requires Kubernetes 1.34 or later, the DRA Consumable Capacity feature gate, CDI and an NVIDIA driver version 440 or newer. Installation uses Helm and requires Kubernetes, Helm, kubectl and installation permissions.
Pricing
HAMi — free. This is open-source GPU virtualization middleware for AI workloads on Kubernetes, with no paid tier, seat charge or trial period. The free plan gives every user the complete project distribution, but operating costs remain your responsibility because deployment is self-hosted. Choose it when you have Kubernetes expertise and want to control infrastructure directly; choose a managed service instead if you need someone else to run the cluster.
Platforms
HAMi runs on Linux in a self-hosted deployment model. Kubernetes is required, with the version and driver prerequisites depending on whether you use classic HAMi or HAMi-DRA.
Who it's for
HAMi fits platform engineers and research teams sharing heterogeneous accelerators among LLM, machine-learning and HPC workloads. It is particularly compelling when GPU memory and core quotas, Prometheus visibility and Kubernetes-native scheduling matter more than a turnkey control plane. It is a poor fit for workloads that require uniform hardware isolation, guaranteed partition boundaries or strict compliance controls across every supported device.
Pros and cons
- Pro: Broad accelerator coverage helps mixed-hardware Kubernetes clusters avoid adopting a separate sharing layer for each vendor.
- Pro: Memory and compute quotas, multiple placement policies and Prometheus-scrapable metrics support practical multi-tenant operations.
- Pro: The software is free and open source, with documentation, tutorials, Discord and the #hami-dev Slack channel for community support.
- Con: Isolation is soft and best-effort in important cases, and CUDA-bypassing applications are not covered by NVIDIA interception.
- Con: Device capabilities are uneven; some listed accelerators lack memory isolation, core isolation or multi-card partitioning.
- Con: Native priority handling stops at two levels, so complex queue policies add a Volcano integration.
- Con: The newer DRA path has demanding Kubernetes and driver prerequisites, which can complicate adoption on older clusters.
Alternatives
dstack is a better match when you want an open-source orchestration stack across Linux, macOS, Windows, web and API environments, with an optional GPU marketplace billed by usage.
ClearML suits teams wanting a freemium platform with a self-hosted version described as fully open source, plus a no-credit-card Community plan.
GPUStack is worth choosing when a free, open-source GPU cluster manager is the priority across desktop, web, API and self-hosted platforms.
Backend.AI is preferable if you want freemium options, including a free self-hosted edition and a trial plan.
TORQUE Resource Manager is a conventional open-source resource manager for Linux, macOS and self-hosted deployments.
HTCondor is another free cluster-management choice spanning self-hosted and web environments.
Kueue is the focused alternative when you need an open-source Kubernetes queueing project rather than accelerator virtualization middleware.
NVIDIA ShadowPlay targets Windows capture and gaming workflows, not Kubernetes GPU-cluster management.
See the GPU Cluster Management Software list for more options.
Verdict
Choose HAMi if you operate a Kubernetes cluster and need free, vendor-broad accelerator sharing with quotas, scheduling and utilization metrics. Look elsewhere when your workloads demand hardware-enforced isolation, consistent partition features across devices or a managed deployment; HAMi’s best-effort boundaries and self-hosted operational burden are decisive limitations.