DreamTalk
DreamTalk is a free, open-source, self-hosted framework for generating expressive talking-head videos from audio.
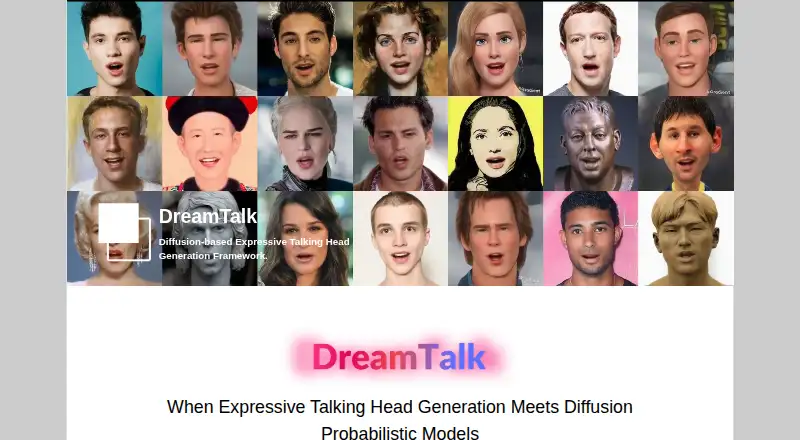
What DreamTalk is
DreamTalk is a free, open-source, self-hosted framework for generating expressive talking-head videos from audio. It combines a denoising network, a style-aware lip expert, and a style predictor. The predictor infers a target speaking style from audio without requiring an expression reference video or text, while classifier-free guidance and style-code interpolation provide style controls. Inference accepts WAV, MP3, M4A, or MP4 audio, a portrait, and 3DMM parameter sequences for speaking style and head pose. Portraits should exceed 256×256 pixels, are cropped to 256×256, and frontal images are described as usually suitable. Motion references come from 25 FPS video. Generated videos are saved as MP4 files, and a configurable duration limit truncates longer audio. Examples cover Chinese, French, German, Italian, Japanese, Korean, and Spanish speech, plus songs and noisy audio. CPU use is available with the listed argument. Public checkpoint downloads have ceased, with academic requests handled by email.
Good
- Free and open source
- Infers speaking style from audio alone
- Accepts four listed audio formats
- Supports seven speech languages in examples
- Can run on CPU with the listed argument
Watch out
- Intended for research and non-commercial use
- Public checkpoint downloads have ceased
- Portraits are cropped to 256×256
- Audio beyond the configured duration is truncated
Who it suits
DreamTalk suits researchers and developers who can run a self-hosted Python and PyTorch environment for non-commercial work. It is also relevant to users working with multilingual speech, songs, noisy audio, or configurable speaking styles.
Verdict
DreamTalk provides an open framework for audio-driven talking-head generation with style controls and broad example coverage. Self-hosting, unavailable public checkpoints, and the research-only restriction are central considerations before adopting it.
The facts
Each one read from DreamTalk's own pages, with the date it was checked.
What it does
- Checkpoint access
- Public checkpoint downloads have been discontinued; the README asks researchers to request checkpoints by email and states that doing so implies consent to use them solely for academic research.checked 9 Oct 2026
- CPU support
- The repository says the program can run on CPU by adding the --device=cpu argument.checked 4 Oct 2026
- Duration limit
- The max_gen_len setting controls the maximum generated video duration in seconds, and longer input audio is truncated.checked 9 Oct 2026
- Expressions
- Its style predictor predicts a target expression from audio without requiring an expression reference video or text.checked 9 Oct 2026
- How it works
- The framework combines a denoising network, a style-aware lip expert, and a style predictor.checked 9 Oct 2026
- Inference inputs
- Inference accepts WAV, MP3, M4A, or MP4 audio, a portrait image, and reference 3DMM sequences for speaking style and head pose.checked 9 Oct 2026
- Input audio
- The inference instructions list WAV, MP3, M4A, and MP4 files with sound as compatible audio inputs.checked 4 Oct 2026
- Input coverage
- The project reports generalization across songs, noisy audio, out-of-domain portraits, and speech in Chinese, French, German, Italian, Japanese, Korean, and Spanish.checked 9 Oct 2026
- Languages and audio
- The project page lists speech examples in Chinese, French, German, Italian, Japanese, Korean, and Spanish, as well as songs and noisy audio.checked 4 Oct 2026
- License
- The repository includes an MIT license, while its README says the method is intended for research and non-commercial use only.checked 9 Oct 2026
- Maintainers
- The project page lists authors affiliated with Tsinghua University, Alibaba Group, and Huazhong University of Science and Technology.checked 9 Oct 2026
- Motion references
- Speaking-style and head-pose references use 3DMM parameter sequences extracted from videos, and the stated video frame rate is 25 FPS.checked 4 Oct 2026
- Output
- The inference script saves the generated video as an MP4 file in the output_video folder.checked 4 Oct 2026
- Portrait requirements
- The input portrait should be larger than 256×256 pixels; the instructions say frontal portraits usually produce satisfactory results and are cropped to 256×256.checked 4 Oct 2026
- Purpose
- DreamTalk is a diffusion-based framework for generating expressive talking-head videos from audio.checked 9 Oct 2026
- Resolution
- The README says resolution was not considered in the initial design and describes optional super-resolution methods with tradeoffs in speed, temporal consistency, or facial emotion intensity.checked 9 Oct 2026
- Setup
- The repository provides inference code and installation instructions for a Python 3.7 environment with PyTorch 1.8.0 and CUDA 11.1 packages.checked 9 Oct 2026
- Speaking styles
- The project demonstrates speaking-style manipulation by adjusting classifier-free guidance and interpolating style codes.checked 9 Oct 2026
- Style prediction
- Its style predictor can infer a target speaking style from audio without an expression reference video or text.checked 4 Oct 2026
- Support
- The project page invites researchers interested in joining the team to email a resume to [email protected].checked 9 Oct 2026
- Use restriction
- The repository states that the method is intended for research and non-commercial use only.checked 4 Oct 2026
- What it does
- DreamTalk is a diffusion-based framework for generating expressive talking-head videos from audio.checked 4 Oct 2026
The company
- Founded
- 2023checked 28 Sep 2026
Where it runs
- Generation approach
- The framework combines a denoising network, a style-aware lip expert, and a style predictor.checked 4 Oct 2026
Alternatives to DreamTalk
- 1
Sync Labs
Free planAndroidiOSWebAPI8.0From $5 a month - 2
Morph Studio
Free planiOSWeb7.8From $12 a month - 3
VEED
Free planAndroidiOSWebExtension7.5Free plan - 4
Muse
Free planOpen sourceLinuxmacOSSelf-hostedWindows7.4Free plan - 5
CHAMELAION LipSync API
Free planWebAPI7.3From €5 a month - 6
lipsyn.cc
Free planWebAPI7.3€11.99 one-time