StyleTTS 2
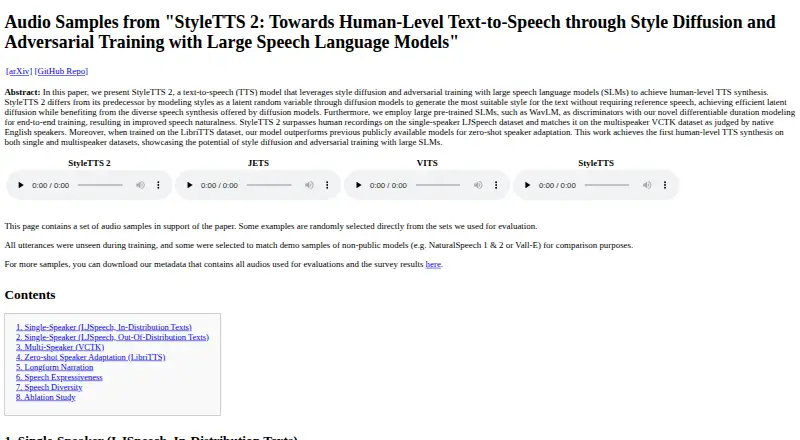
The facts below are what the maker publishes about StyleTTS 2, checked and dated. Our editors have not written about it yet.
The facts
Each one read from StyleTTS 2's own pages, with the date it was checked.
What it does
- Code license
- The repository states that its code is licensed under the MIT License.checked 13 Oct 2026
- Compute requirements
- The repository notes that training or inference can run into out-of-memory issues and recommends reducing batch size or maximum audio length; it also says older GPUs may produce background noise.checked 13 Oct 2026
- Dependencies
- The repository says its inference depends on a GPL-licensed package that is not included directly, and also links to a fully MIT-licensed package using gruut with lower output quality due to a phonemizer mismatch.checked 13 Oct 2026
- Evaluation
- The makers report that StyleTTS 2 surpasses human recordings on single-speaker LJSpeech and matches them on multispeaker VCTK, as judged by native English speakers.checked 12 Oct 2026
- Expressiveness
- The sample page demonstrates expressive speech, style transfer, longform narration, and speech diversity.checked 13 Oct 2026
- Inference
- The repository provides inference notebooks and pretrained model downloads for LJSpeech and LibriTTS.checked 13 Oct 2026
- Installation
- The repository lists Python 3.7 or newer as a prerequisite and gives additional installation instructions for Windows.checked 13 Oct 2026
- Known limitation
- The repository says the distributed-data-parallel version of second-stage training does not work, so the current version uses data parallelism.checked 13 Oct 2026
- Language support
- The repository says non-English training requires a pretrained PL-BERT model for the language and points to a multilingual PL-BERT supporting 14 languages.checked 13 Oct 2026
- Limitations
- The README says the second-stage training code uses data parallelism because its distributed data parallel version does not work.checked 12 Oct 2026
- Model use
- For pretrained models, the repository asks users to disclose synthesized speech unless they have permission to use the cloned voice, and says public voice use requires speaker permission or disclosure.checked 13 Oct 2026
- Online demo
- The repository links to a Hugging Face online demo.checked 13 Oct 2026
- Open source license
- The repository code is licensed under the MIT License.checked 12 Oct 2026
- Pretrained models
- The repository links pretrained models for LJSpeech and LibriTTS.checked 12 Oct 2026
- Purpose
- StyleTTS 2 is a text-to-speech model that uses style diffusion and adversarial training with large speech language models.checked 13 Oct 2026
- Speaker adaptation
- The project reports that its LibriTTS-trained model outperforms previous publicly available models for zero-shot speaker adaptation.checked 13 Oct 2026
- Speech naturalness
- The model uses pre-trained speech language models such as WavLM as discriminators and differentiable duration modeling to improve speech naturalness.checked 12 Oct 2026
- Speech quality
- The authors report that it surpasses human recordings on the single-speaker LJSpeech dataset and matches them on multispeaker VCTK, as judged by native English speakers.checked 13 Oct 2026
- Style generation
- It models speaking styles as latent random variables and uses diffusion to generate a suitable style without reference speech.checked 13 Oct 2026
- Style transfer
- The model can transfer an emotional style sampled from emotional text to input text that has no emotional content.checked 12 Oct 2026
- Voice cloning
- Yeschecked 20 Sep 2026
- Voice use terms
- For pretrained models, the README says users must have permission to clone a speaker's voice or publicly disclose that the generated voice is synthesized.checked 12 Oct 2026
Where it runs
- Linux dependency
- The demo instructions say to install phonemizer and espeak-ng; the example espeak-ng command uses apt-get.checked 12 Oct 2026
- Platforms
- windows,linux,self_hostedchecked 20 Sep 2026
Alternatives to StyleTTS 2
- 1
Voicebox
Free planOpen sourceAndroidiOSWebAPI9.3From $12 a year - 2
Speechify
Free planAndroidiOSWebAPI9.0From $10 a month - 3
Resemble AI
Free planAndroidiOSWebAPI9.0From $280 a month - 4
iSpeech
Free planOpen sourceAndroidiOSWebAPI9.0Free plan - 5
Fliki
Free planAndroidiOSWebAPI8.8From $28 a month - 6
Voice.ai
Free planAndroidiOSWebAPI8.8From $5 a month