NNSVS
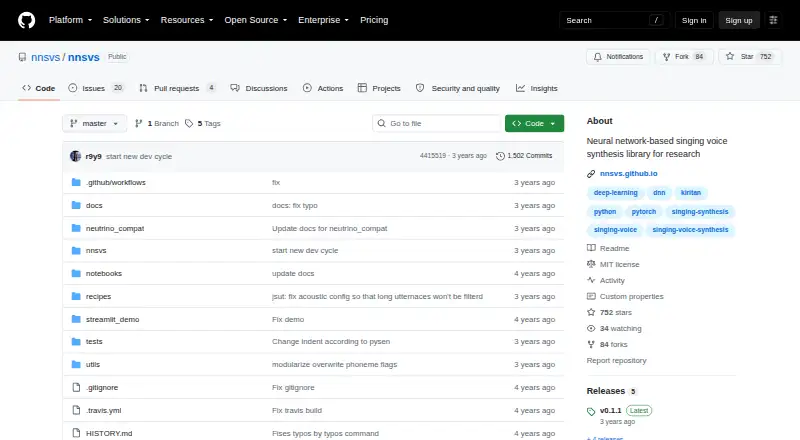
NNSVS is an open-source library for creating neural network-based singing voice synthesis systems, designed for research.
What NNSVS is
NNSVS is an open-source library for creating neural network-based singing voice synthesis systems, designed for research. It lets users build voicebanks from their own datasets and provides reproducible research recipes modeled on Kaldi and ESPnet. The recipes cover preprocessing, training, and synthesis and can be adapted to custom data and models. With a packed model, users can generate singing voice from MusicXML or UST files; WAV is the listed export format. The documented synthesis pipeline includes time-lag, duration, acoustic, post-filter, and vocoder modules. Users can implement custom PyTorch models through the NNSVS BaseModel interface. Optuna supports hyperparameter optimization, and MLflow tracks and visualizes search results. The documentation describes singing voice systems created with NNSVS for eight or more languages. It runs on Linux, Mac OS X, and Windows, with Linux recommended for development. Installation requires Python 3.7 or later and a C/C++ compiler; GPU/CUDA is strongly recommended for performance. Google Colab is an option for users without a GPU, but is not recommended for hyperparameter optimization. Acoustic model training can take several hours or a whole day, depending on configuration. The project is MIT-licensed, and commercial use is allowed.
Good
- Free and open source under the MIT license.
- Recipes cover preprocessing, training, and synthesis.
- Accepts MusicXML or UST with packed models.
- Runs on Linux, Mac OS X, and Windows.
Watch out
- Requires Python 3.7 or later and a C/C++ compiler.
- GPU/CUDA is strongly recommended for performance.
- Acoustic model training can take hours or a day.
- Post-filter is not recommended; neural-vocoder support is limited.
Who it suits
NNSVS is aimed at researchers and developers building or customizing singing voice synthesis systems. The project points non-researchers and non-developers toward more user-friendly tools such as ENUNU and Simple-ENUNU.
Verdict
NNSVS provides a customizable research workflow for singing voice synthesis, with recipes, integrations, and support for custom models. Its research focus, compute requirements, and potentially lengthy training make it a better fit for technical users than people seeking a simple singing app.
The facts
Each one read from NNSVS's own pages, with the date it was checked.
What it does
- Compute
- GPU/CUDA is strongly recommended for performance, while Google Colab is listed as an option for users without GPUs.checked 8 Oct 2026
- Customization
- Users can implement custom PyTorch models by inheriting NNSVS's BaseModel interface.checked 8 Oct 2026
- Input formats
- Packed models can generate singing voice from MusicXML or UST files.checked 7 Oct 2026
- Inputs and outputs
- With a packed model, users can generate singing voice by inputting MusicXML or UST files.checked 8 Oct 2026
- Integrations
- NNSVS integrates Optuna for hyperparameter optimization and uses MLflow to visualize and track search results.checked 7 Oct 2026
- Intended users
- The project says it was originally designed for research and recommends other tools for users who are neither researchers nor software developers.checked 8 Oct 2026
- Languages
- NNSVS has been used to create singing voice synthesis systems for multiple languages, with the documentation saying 8 or more as far as its author knows.checked 8 Oct 2026
- Licensing
- The project’s GitHub repository lists the MIT license.checked 7 Oct 2026
- Notable limitation
- The documentation says the post-filter is currently not recommended and neural-vocoder support is limited.checked 8 Oct 2026
- Open source
- NNSVS is fully open-source, and users can create their own voicebanks with their dataset.checked 8 Oct 2026
- Optional compute
- Users without a GPU can run NNSVS on Google Colab, though the documentation does not recommend Colab for hyperparameter optimization.checked 7 Oct 2026
- Purpose
- NNSVS is a neural network based singing voice synthesis library designed for research.checked 8 Oct 2026
- Requirements
- The guide specifies Python 3.7 or later and says a C/C++ compiler must be installed in advance.checked 8 Oct 2026
- Research recipes
- It includes reproducible Kaldi and ESPnet style recipes for creating baseline systems in research.checked 7 Oct 2026
- Research workflows
- NNSVS includes reproducible recipes modeled on Kaldi and ESPnet approaches for building baseline systems in research.checked 8 Oct 2026
- Supported operating systems
- The installation guide lists Linux, Mac OS X, and Windows as supported platforms and says Linux is recommended for development.checked 7 Oct 2026
- Support information
- The opened project pages provide installation guides, tutorials, and API reference documentation; they do not state a dedicated support service.checked 7 Oct 2026
- Synthesis pipeline
- Its documented system includes time-lag, duration, acoustic, post-filter, and vocoder modules.checked 8 Oct 2026
- Training limitation
- The documentation says acoustic model training can take several hours or a whole day depending on configuration.checked 7 Oct 2026
- Workflow
- Recipes cover data preprocessing, training, and synthesis, and can be customized with users’ own data and models.checked 7 Oct 2026
Where it runs
- Supported platforms
- The installation guide lists Linux, Mac OS X, and Windows as supported and says NNSVS is tested on them with GitHub Actions.checked 8 Oct 2026
Alternatives to NNSVS
- 1
Revocalize AI
Free planAndroidiOSWebAPI8.1From $9 a month - 2
SightSinger
Free planAndroidiOSWebmacOS8.0Free plan - 3
Kits AI
Free planWebAPIWindows7.7From $10 a month - 4
VoiSona Song
Free planiOSmacOSWindows7.6From ¥6,600 a year - 5
Audimee
Free planWebAPI7.5From $9 a month - 6
Tunela
Free planWeb7.4From $10.99 a month