Mozilla Document-to-Podcast
Mozilla Document-to-Podcast is an open-source Mozilla.ai blueprint that turns documents into a podcast with two speakers.
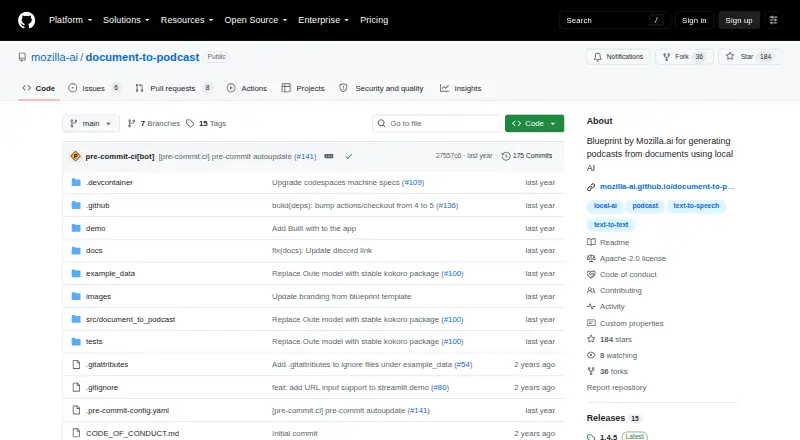
What Mozilla Document-to-Podcast is
Mozilla Document-to-Podcast is an open-source Mozilla.ai blueprint that turns documents into a podcast with two speakers. Its workflow extracts and cleans document text, uses a language model to create a conversational script, then generates audio with text-to-speech. The command-line interface accepts PDF, HTML, TXT, DOCX, and Markdown files and saves podcast.txt and podcast.wav in the selected output folder. Users can customize prompts, speaker names and roles, descriptions, voice profiles, and model settings. The project also provides a Streamlit graphical demo, and can be installed from PyPI or in editable mode from a clone. It is designed for local processing without external API calls or GPU access. Users can select text-to-text models loadable by llama.cpp; Kokoro-82M is supported out of the box. The stated requirements include Windows, macOS, or Linux, Python 3.10 or later (3.12 or later for Apple M chips), at least 8 GB RAM, and at least 20 GB disk space. If cleaned text exceeds the model’s context-based character limit, the CLI may use only part of it.
Good
- Accepts PDF, HTML, TXT, DOCX, and Markdown.
- Saves both a text script and WAV audio.
- Offers CLI and Streamlit demo interfaces.
- Designed to process files locally without external API calls.
- Speaker voices and script prompts are customizable.
Watch out
- Requires at least 8 GB RAM and 20 GB disk space.
- Apple M chips require Python 3.12 or later.
- Long cleaned text may be only partly used.
Who it suits
This blueprint may suit developers who want to integrate open-source AI tools into projects or create two-speaker audio from documents. Users should be comfortable with its stated system requirements and model setup options.
Verdict
Document-to-Podcast provides a customizable local workflow for turning supported documents into scripted, two-speaker audio. Check the system requirements and context-length limitation when choosing it for longer files.
The facts
Each one read from Mozilla Document-to-Podcast's own pages, with the date it was checked.
What it does
- Cloud setup options
- The getting-started guide lists Google Colab, GitHub Codespaces, and local installation as setup options.checked 7 Oct 2026
- Customization
- Users can customize the script prompt, speakers, voice profiles, and model settings.checked 4 Oct 2026
- Document formats
- The documented pipeline accepts PDF, HTML, TXT, DOCX, and Markdown files.checked 7 Oct 2026
- Input formats
- The CLI accepts PDF, HTML, TXT, DOCX, and Markdown files.checked 4 Oct 2026
- Installation
- The project can be installed from PyPI with pip or cloned and installed in editable mode.checked 4 Oct 2026
- Interfaces
- The project offers a command-line interface and a Streamlit graphical demo app.checked 7 Oct 2026
- License
- The project is licensed under Apache 2.0.checked 7 Oct 2026
- Local processing
- The project is designed to run on local setups without external API calls or GPU access, keeping processing local.checked 7 Oct 2026
- Model choice
- Users can select a text-to-text model loadable by llama.cpp and can use the supported Kokoro-82M text-to-speech model out of the box.checked 7 Oct 2026
- Model support
- Users can select text-to-text models loadable by llama.cpp and supported text-to-speech loaders; Kokoro-82M is listed as currently supported out of the box.checked 4 Oct 2026
- Output files
- The CLI writes a podcast script as podcast.txt and audio as podcast.wav in the specified output folder.checked 7 Oct 2026
- Pipeline
- The documented workflow extracts and cleans document text, generates a conversational script with a language model, then creates audio with text-to-speech.checked 4 Oct 2026
- Privacy
- The project describes local processing without external API calls as a way to keep processing local and make it more privacy-friendly.checked 4 Oct 2026
- Purpose
- Document-to-Podcast is a Mozilla.ai Blueprint for turning input documents into podcasts featuring two speakers.checked 7 Oct 2026
- Speaker voices
- Each speaker can have a distinct voice profile, and speaker names, roles, descriptions, and voice profiles are customizable.checked 7 Oct 2026
- Support
- The README directs users with issues to the troubleshooting documentation before opening a new issue, and the docs invite questions on Discord.checked 7 Oct 2026
- Supported operating systems
- The stated system requirements list Windows, macOS, and Linux, Python 3.10 or later (3.12 or later for Apple M chips), at least 8 GB RAM, and at least 20 GB disk space.checked 4 Oct 2026
- System requirements
- The README lists Windows, macOS, or Linux, Python 3.10 or later (3.12 or later for Apple M chips), at least 8 GB RAM, and 20 GB disk space.checked 7 Oct 2026
- Target audience
- The project describes Blueprints as tools for developers to integrate AI capabilities into their projects using open-source models and tools.checked 7 Oct 2026
- Usage limit
- The CLI may use only a subset of the input when cleaned text exceeds the text model's context-based character limit.checked 4 Oct 2026
- Workflow
- The pipeline extracts and cleans document text, generates a conversational script with a language model, then creates audio with text-to-speech.checked 7 Oct 2026