HunyuanVideo
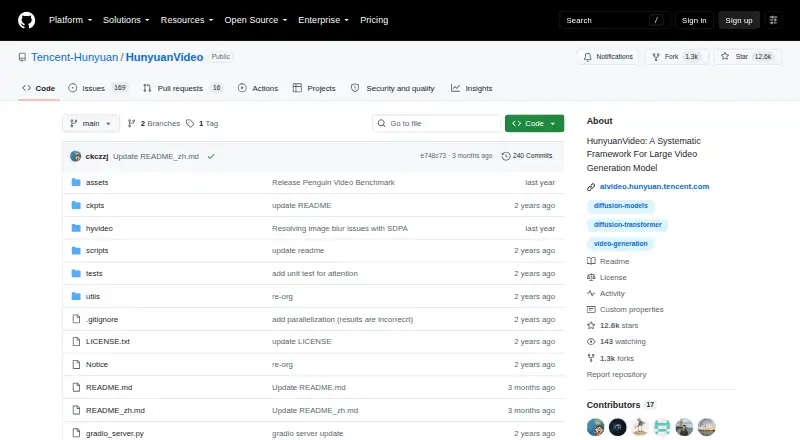
HunyuanVideo is an open-source video foundation model with code and pretrained weights for generating video from text prompts or images.
What HunyuanVideo is
HunyuanVideo is an open-source video foundation model with code and pretrained weights for generating video from text prompts or images. The repository provides PyTorch definitions, inference tools, and sampling code, with generation configurations at 540p and 720p using 129 frames; the listed maximum resolution is 1080p. The model has over 13 billion parameters and uses a decoder-only multimodal language model as its text encoder. Its unified architecture combines dual-stream and single-stream Transformer designs with full attention. Prompt rewriting offers Normal and Master modes, with Master adding composition, lighting, and camera movement detail while potentially losing semantic details. FP8 weights can reduce GPU memory use by about 10GB. HunyuanVideo requires an NVIDIA CUDA GPU; stated peaks are 60GB for 720p and 45GB for 544p generation. Linux is the tested operating system, with Docker images and a Linux guide. Commercial use is supported.
Good
- Open-source code and pretrained weights
- Supports text-to-video and image-to-video generation
- Commercial use is permitted
- FP8 weights reduce memory requirements
- Integrates with Diffusers and community ComfyUI tools
Watch out
- Requires NVIDIA GPU with CUDA
- Peak memory reaches 60GB for listed mode
- Linux is the tested operating system
- No API access or AI avatars
Who it suits
It suits technically capable users running Linux with NVIDIA CUDA hardware who want open-source text-to-video or image-to-video generation. Commercial projects are allowed, while users needing avatars or an API should note their absence.
Verdict
HunyuanVideo offers a substantial, self-hosted video-generation model for Linux hardware with sufficient GPU memory. Its open-source workflow and commercial use are useful, but the demanding hardware and missing API limit who can deploy it.
The facts
Each one read from HunyuanVideo's own pages, with the date it was checked.
What it does
- AI avatars
- Nochecked 19 Sep 2026
- API access
- Nochecked 19 Sep 2026
- Architecture
- The model uses a unified image and video generative architecture with a hybrid dual-stream to single-stream Transformer design and full attention.checked 11 Oct 2026
- Commercial use
- Yeschecked 19 Sep 2026
- Community tools
- The project lists community contributions including native ComfyUI support and a ComfyUI wrapper.checked 11 Oct 2026
- Downloads
- The project provides inference code and pretrained model weights, with FP8 weights also available to reduce GPU memory use by about 10GB.checked 11 Oct 2026
- Generation
- The repository supports text-prompt video generation at 540p and 720p, with 129-frame configurations.checked 11 Oct 2026
- Hardware requirements
- The model requires an NVIDIA GPU with CUDA; the stated peak GPU memory requirements are 60GB for 720p 129-frame generation and 45GB for 544p 129-frame generation.checked 11 Oct 2026
- Image-to-video
- The project links a separate HunyuanVideo image-to-video model with inference code and checkpoints.checked 11 Oct 2026
- Integrations
- The repository says HunyuanVideo is integrated into Diffusers and offers parallel inference code powered by xDiT.checked 11 Oct 2026
- License
- The repository links a license file, but the opened page does not state license terms in its displayed content.checked 11 Oct 2026
- Lower-memory option
- FP8 quantized weights save about 10GB of GPU memory, according to the repository.checked 11 Oct 2026
- Maximum resolution
- 1080pchecked 19 Sep 2026
- Model size
- The model has over 13 billion parameters.checked 11 Oct 2026
- Operating system
- Linux is the tested operating system, and the repository provides a Linux installation guide and Docker images.checked 11 Oct 2026
- Product
- HunyuanVideo is an open-source video foundation model; the repository provides PyTorch model definitions, pretrained weights, and inference and sampling code.checked 11 Oct 2026
- Prompt rewriting
- Its prompt rewrite model offers Normal and Master modes; the Master mode adds detail about composition, lighting, and camera movement and may lose some semantic details.checked 11 Oct 2026
- Purpose
- HunyuanVideo is an open-source video foundation model with code and pretrained weights for video generation.checked 11 Oct 2026
- Support
- The repository invites users to join its WeChat and Discord communities and to share projects using HunyuanVideo.checked 11 Oct 2026
- Text encoder
- The model uses a decoder-only multimodal large language model as its text encoder.checked 11 Oct 2026
- Text-to-video
- The released model generates videos from text prompts, with supported output settings up to 720p and 129 frames.checked 11 Oct 2026
The company
- Founded
- 1998checked 28 Sep 2026
- Headquarters
- Shenzhen, Chinachecked 28 Sep 2026
- Maker
- Tencent says it was founded in 1998 and is headquartered in Shenzhen, China.checked 11 Oct 2026
Alternatives to HunyuanVideo
- 1

HeyGen
Free planAndroidiOSWebAPI9.1From $24 a month - 2
PixVerse
Free planAndroidiOSWebAPI9.1From $8 a month - 3
Kling AI
Free planAndroidiOSWebAPI9.0From $6.99 a month - 4

InVideo AI
Free planAndroidiOSWebAPI9.0From $4 a month - 5
Pollo AI
Free planAndroidiOSWebAPI9.0Free plan - 6
Visla AI Video Agent
Free planAndroidiOSWebAPI8.9Free plan