GLM-TTS
The facts below are what the maker publishes about GLM-TTS, checked and dated. Our editors have not written about it yet.
The facts
Each one read from GLM-TTS's own pages, with the date it was checked.
What it does
- Deployment hardware
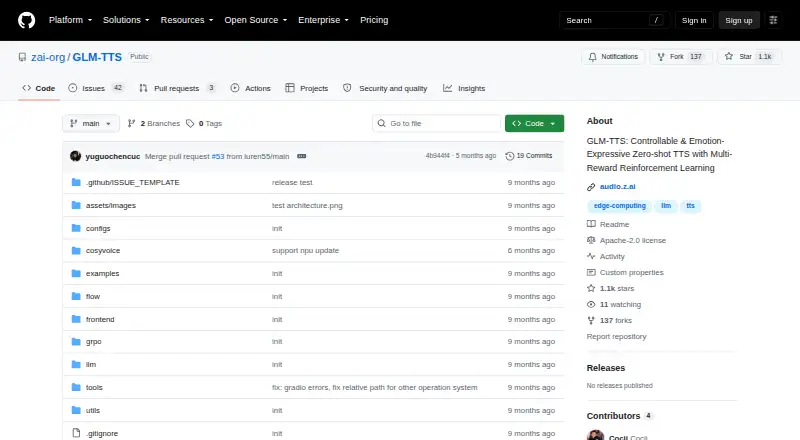
- The repository provides separate setup instructions for GPU and NPU environments.checked 13 Oct 2026
- Emotion control
- Its multi-reward reinforcement learning framework supports emotional expression and prosody control.checked 13 Oct 2026
- Export formats
- WAVchecked 20 Sep 2026
- Hardware and setup
- The setup instructions cover GPU and Ascend NPU environments and specify Python 3.10–3.12.checked 12 Oct 2026
- Inference
- The repository provides command-line and shell-script inference, plus an interactive web interface launched with Gradio.checked 12 Oct 2026
- Inference options
- It supports phoneme-level text-to-speech, multiple sampling strategies, and multiple inference modes.checked 13 Oct 2026
- Integrations
- The project acknowledges CosyVoice for frontend processing and vocoding, Llama as its language-model architecture, and Vocos as a vocoder.checked 12 Oct 2026
- Languages
- It primarily supports Chinese and also supports English mixed text.checked 13 Oct 2026
- License
- The repository identifies its license as Apache-2.0.checked 13 Oct 2026
- Model architecture
- The system uses an LLM to generate speech token sequences and a Flow model to convert tokens into audio waveforms.checked 13 Oct 2026
- Model downloads
- The complete model weights can be downloaded from Hugging Face or ModelScope.checked 13 Oct 2026
- Product
- GLM-TTS is a large-language-model-based text-to-speech system that supports zero-shot voice cloning and streaming inference.checked 12 Oct 2026
- Pronunciation
- Phoneme-in supports hybrid phoneme and text input to control pronunciation of specific words, including polyphones and rare characters.checked 12 Oct 2026
- Purpose
- GLM-TTS is a text-to-speech synthesis system based on large language models.checked 13 Oct 2026
- Requirements
- The quick-start instructions specify Python 3.10 through 3.12.checked 13 Oct 2026
- Security
- The repository page does not state security certifications or compliance claims.checked 12 Oct 2026
- Streaming
- It supports real-time streaming audio generation for interactive applications.checked 13 Oct 2026
- Support
- The project links to a technical report, Hugging Face, ModelScope, and an Audio.Z.AI site; the repository page does not specify a support service.checked 12 Oct 2026
- Upcoming work
- The README lists a 2D Vocos vocoder update and reinforcement-learning-optimized model weights as coming soon.checked 13 Oct 2026
- Voice cloning
- It supports zero-shot voice cloning from 3–10 seconds of prompt audio.checked 13 Oct 2026
- Web interface
- The repository includes instructions for running an interactive web interface with Gradio.checked 13 Oct 2026
Where it runs
- Platforms
- web,self_hostedchecked 20 Sep 2026
Alternatives to GLM-TTS
- 1
Voicebox
Free planOpen sourceAndroidiOSWebAPI9.3From $12 a year - 2
Speechify
Free planAndroidiOSWebAPI9.0From $10 a month - 3
Resemble AI
Free planAndroidiOSWebAPI9.0From $280 a month - 4
iSpeech
Free planOpen sourceAndroidiOSWebAPI9.0Free plan - 5
Fliki
Free planAndroidiOSWebAPI8.8From $28 a month - 6
Voice.ai
Free planAndroidiOSWebAPI8.8From $5 a month