F5-TTS
C
C tier on Text-to-Speech SoftwareScore 6.4 · #82 of 216
- Android app
- Not listed
- Free plan
- No
- Runs on
- api, Linux, Mac, self-hosted, Web
Summary
F5-TTS is ranked #82 of 216 in text-to-speech software on Everything Xiaomi. It runs on API, Linux, macOS, Self-hosted, Web.
Compared on text-to-speech software
- Commercial use
- Nogithub.com
- Voice cloning
- Yesgithub.com
- API access
- Yesgithub.com
Facts
- Platforms
- Web, Linux, macOS, API, self_hostedgithub.com · 20 Sept 2026
- Purpose
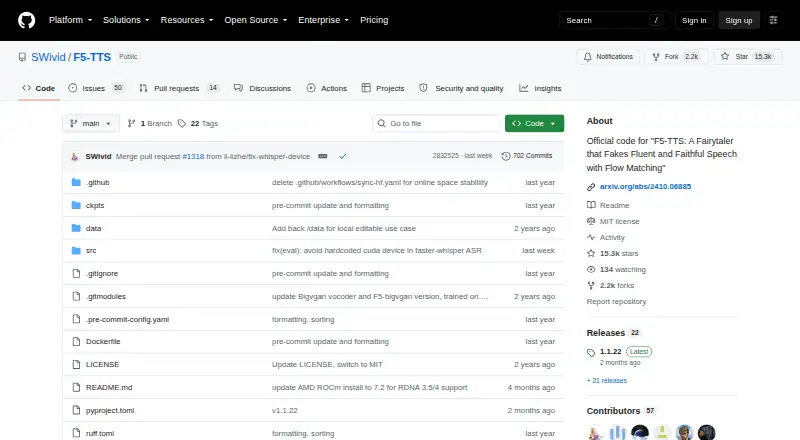
- F5-TTS is an open-source text-to-speech project that uses flow matching to generate fluent and faithful speech.github.com · 8 Oct 2026
- Model design
- The project describes F5-TTS as a Diffusion Transformer with ConvNeXt V2 and includes E2 TTS, a Flat-UNet Transformer.github.com · 8 Oct 2026
- Inference features
- The Gradio app supports basic text-to-speech with chunk inference, multi-style and multi-speaker generation, and voice chat powered by Qwen2.5-3B-Instruct.github.com · 8 Oct 2026
- Custom languages
- The README links to custom inference instructions for adding language support.github.com · 8 Oct 2026
- Ways to run
- The project can be installed as a Python package, run from a local editable clone, or built and run with Docker.github.com · 8 Oct 2026
- Web interface
- The project provides Gradio commands for launching a web interface and a share link.github.com · 8 Oct 2026
- Training
- Training and fine-tuning are supported through Hugging Face Accelerate or a Gradio app.github.com · 8 Oct 2026
- Hardware requirements
- The installation instructions cover NVIDIA, AMD, Intel, and Apple Silicon setups; the AMD ROCm instructions specify Linux.github.com · 8 Oct 2026
- Deployment
- The README describes a deployment solution using Triton and TensorRT-LLM.github.com · 8 Oct 2026
- Related tools
- The project acknowledges Vocos and BigVGAN as vocoders and FunASR and faster-whisper among its evaluation tools.github.com · 8 Oct 2026
- License
- The code is released under the MIT License, while the pre-trained models are licensed under CC-BY-NC.github.com · 8 Oct 2026
- Support guidance
- The README recommends searching GitHub issues for help with problems encountered.github.com · 8 Oct 2026
- Interfaces
- The project provides a Gradio web interface and command-line inference.github.com · 8 Oct 2026
- Hardware and operating systems
- The installation instructions cover NVIDIA, AMD, and Intel GPUs and Apple Silicon; the AMD ROCm instructions specify Linux.github.com · 8 Oct 2026
- Model availability
- The README links F5-TTS and E2 TTS base models on Hugging Face, Model Scope, and Wisemodel.github.com · 8 Oct 2026
- Runtime benchmark
- The README reports a 253 ms average latency for F5-TTS Base with Vocos at concurrency 2 on a single L20 GPU in its stated benchmark setup.github.com · 8 Oct 2026
- Requirements
- The installation instructions call for Python 3.10 or newer and FFmpeg.github.com · 8 Oct 2026
Best F5-TTS alternatives
See all 20
Where it ranks on Everything Xiaomi
- Best Text-to-Speech Software in 2026#82 of 216
- Best Game Voice Generators in 2026#24 of 42
- Best Voice Cloning Software in 2026#15 of 24
Is F5-TTS yours?
Claim it for free: prove the domain, then correct facts, plans and screenshots. An editor reviews every change.
Sources
- github.com/SWivid/F5-TTS· checked 20 Sept 2026