DiffSinger
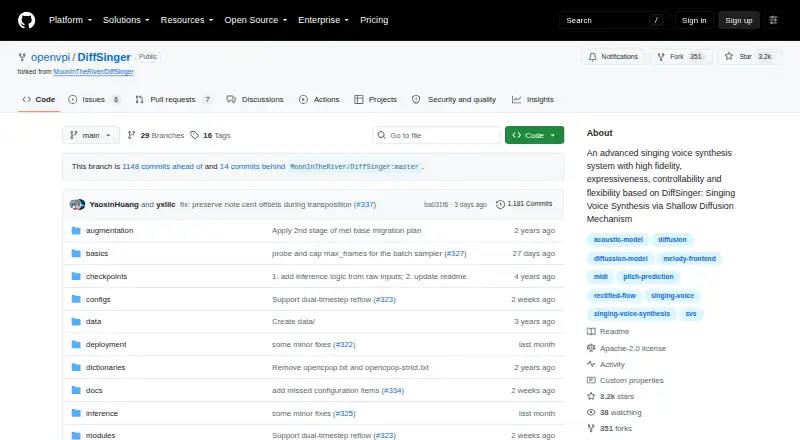
DiffSinger is a self-hosted singing voice synthesis system built around a shallow diffusion mechanism.
What DiffSinger is
DiffSinger is a self-hosted singing voice synthesis system built around a shallow diffusion mechanism. Its maintained version adapts synthesized audio to a 44.1 kHz sampling rate instead of the original 24 kHz. The project integrates improved acoustic models and diffusion sampling acceleration algorithms. Variance models and parameters let users predict and control pitch, energy, breathiness, and other aspects of a voice. The documented workflow covers preparing datasets, training models, and running inference on DS files with variance or acoustic models. The linked MakeDiffSinger project supplies dataset-building pipelines, including recording slicing and labeling tools. Installation requires Python 3.10 or later, and PyTorch 2.4.0 or later is recommended. ONNX is the deployment format. The repository links OpenUtau and DiffScope as production or deployment projects; DiffScope is an editor powered by DiffSinger and remains under development. Users prepare their own data and assets. The project prohibits generating someone's voice without consent, and its guide includes a utility to remove speaker embeddings from checkpoints when distributing models. The repository is Apache-2.0 licensed.
Good
- Controls pitch, energy, and breathiness
- Includes dataset-building tools through MakeDiffSinger
- Uses ONNX for deployment
- Apache-2.0 licensed repository
Watch out
- Requires Python 3.10 or later
- Users must prepare their own data and assets
- DiffScope is still under development
Who it suits
DiffSinger is aimed at the singing voice synthesis community and production deployment. It suits users prepared to work with their own data and assets and follow the documented Python-based workflow.
Verdict
DiffSinger provides a configurable synthesis and training workflow for users prepared to supply and prepare their own materials. Its Python requirements and self-hosted setup are important considerations.
Plans and prices
From DiffSinger's own pricing page, checked 4 Oct 2026.
| Plan | Price | What it gives you |
|---|---|---|
| DiffSinger | Free | Apache-2.0 licensed repository · requires Python 3.10 or later · users prepare their own data and assets |
The facts
Each one read from DiffSinger's own pages, with the date it was checked.
What it does
- Audio quality
- The maintained version adapts synthesized audio to a 44.1 kHz sampling rate instead of the original 24 kHz.checked 4 Oct 2026
- Control
- Variance models and parameters allow prediction and control of pitch, energy, breathiness, and other aspects.checked 4 Oct 2026
- Dataset tools
- The linked MakeDiffSinger project provides pipelines and tools for building DiffSinger datasets, including recording slicing and labeling tools.checked 4 Oct 2026
- Deployment
- The guide states that DiffSinger uses ONNX as its deployment format.checked 4 Oct 2026
- Editor integration
- The repository links OpenUtau and DiffScope as deployment or production projects; DiffScope is described as an editor powered by DiffSinger and is under development.checked 4 Oct 2026
- Installation
- The getting-started guide requires Python 3.10 or later and recommends PyTorch 2.4.0 or later.checked 4 Oct 2026
- Intended users
- The project says its functionality is designed for production deployment and the singing voice synthesis community.checked 4 Oct 2026
- Model distribution
- The getting-started guide includes a utility to remove speaker embeddings from a checkpoint for data security when distributing models.checked 4 Oct 2026
- Model improvements
- The project integrates improved acoustic models and diffusion sampling acceleration algorithms.checked 4 Oct 2026
- Purpose
- DiffSinger is a singing voice synthesis system based on a shallow diffusion mechanism.checked 4 Oct 2026
- Security and consent
- The repository prohibits using its functionality to generate someone's voice without that person's consent.checked 4 Oct 2026
- Support
- The project points users to tutorials, GitHub issues and discussions, and QQ and Discord communication groups.checked 4 Oct 2026
- Training and inference
- The guide describes preprocessing datasets, training models, and running inference on DS files using variance or acoustic models.checked 4 Oct 2026
Alternatives to DiffSinger
- 1
Revocalize AI
Free planAndroidiOSWebAPI8.1From $9 a month - 2
SightSinger
Free planAndroidiOSWebmacOS8.0Free plan - 3
Kits AI
Free planWebAPIWindows7.7From $10 a month - 4
VoiSona Song
Free planiOSmacOSWindows7.6From ¥6,600 a year - 5
Audimee
Free planWebAPI7.5From $9 a month - 6
Tunela
Free planWeb7.4From $10.99 a month