ClearerVoice-Studio
ClearerVoice-Studio is a free, open-source AI toolkit for speech processing.
What ClearerVoice-Studio is
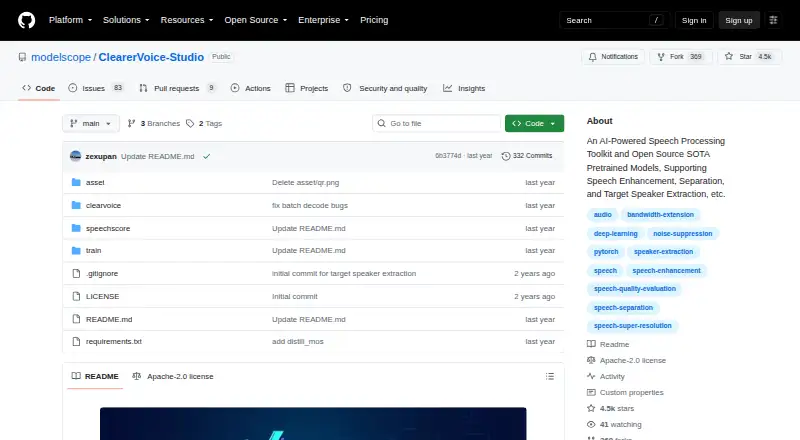
ClearerVoice-Studio is a free, open-source AI toolkit for speech processing. Its tasks include speech enhancement, separation, super-resolution, and audio-visual target-speaker extraction. The project supplies pretrained models for these tasks and scripts for training or fine-tuning them. It also includes SpeechScore for intrusive and non-intrusive speech-quality assessment, with metrics such as PESQ, DNSMOS, SNR, and SI-SDR. The toolkit supports batch processing of audio and video through a Python interface that accepts file paths, directories, or `.scp` lists, as well as a NumPy input-to-output interface. Listed audio formats include WAV, AAC, AC3, AIFF, FLAC, M4A, MP3, OGG, OPUS, WMA, and WEBM; FFmpeg is required for codecs beyond WAV. Installation is available through `pip install clearvoice` or from the GitHub repository. During inference, pretrained models are fetched from Hugging Face, with ModelScope available for manual downloads. The repository links to demos and is released under Apache License, Version 2.0.
Good
- Covers four speech-processing tasks
- Includes pretrained models and training scripts
- SpeechScore offers several quality metrics
- Supports batch audio and video processing
- Open source under Apache License 2.0
Watch out
- FFmpeg is required for codecs beyond WAV
- Inference fetches pretrained models from Hugging Face
- Hugging Face demo GPU usage is limited
Who it suits
It suits researchers, developers, and end-users who want speech-processing models, training scripts, or quality-assessment tools. It is available for Linux, macOS, and Windows, including self-hosted and web use.
Verdict
ClearerVoice-Studio combines processing models, training resources, and speech-quality assessment in a free open-source toolkit. Account for its FFmpeg requirement for non-WAV codecs and the model download options when planning use.
The facts
Each one read from ClearerVoice-Studio's own pages, with the date it was checked.
What it does
- Additional task
- ClearVoice also provides speech super-resolution and audio-visual target speaker extraction.checked 9 Oct 2026
- Audio formats
- The repository says ClearVoice supports formats including WAV, AAC, AC3, AIFF, FLAC, M4A, MP3, OGG, OPUS, WMA, and WEBM, and requires FFmpeg for audio codecs.checked 9 Oct 2026
- Installation
- ClearVoice can be installed from PyPI with `pip install clearvoice` or installed from the GitHub repository.checked 9 Oct 2026
- Integration
- The README shows a Python interface that accepts audio or video file paths, directories, or `.scp` lists, and includes a NumPy input-to-output interface.checked 9 Oct 2026
- Intended users
- The repository describes the toolkit as designed for researchers, developers, and end-users.checked 9 Oct 2026
- License
- The GitHub repository identifies its license as Apache-2.0.checked 9 Oct 2026
- Model downloads
- Pretrained models are fetched from Hugging Face during inference, with manual downloads available from ModelScope if automatic downloads fail.checked 9 Oct 2026
- Model hosting
- Pretrained models are fetched from Hugging Face during inference, with ModelScope downloads offered as a manual alternative.checked 4 Oct 2026
- Notable limit
- The README says Hugging Face demo GPU usage is limited and ModelScope has a larger GPU usage quota.checked 4 Oct 2026
- Pretrained models
- The listed pretrained models cover speech enhancement, speech separation, speech super-resolution, and audio-visual target speaker extraction.checked 9 Oct 2026
- Purpose
- ClearerVoice-Studio is an open-source AI speech-processing toolkit with pretrained models for speech enhancement, separation, and target speaker extraction.checked 9 Oct 2026
- Quality assessment
- The included SpeechScore toolkit evaluates speech quality using metrics including SNR, PESQ, STOI, DNSMOS, and SI-SDR.checked 9 Oct 2026
- Speech tasks
- ClearVoice supports speech enhancement, speech separation, speech super-resolution, and audio-visual target-speaker extraction.checked 4 Oct 2026
- Support
- The maintainers invite users to raise repository issues, email the listed contacts, or join their DingTalk group.checked 9 Oct 2026
- Training
- The repository provides training and fine-tuning scripts for speech enhancement, separation, super-resolution, and target speaker extraction.checked 9 Oct 2026
Where it runs
- Demos
- The repository links to ClearVoice demos on Hugging Face and ModelScope, plus a SpeechScore demo on Hugging Face.checked 4 Oct 2026
- Platforms
- The installation instructions describe FFmpeg setup for Ubuntu/Debian, macOS, and Windows.checked 4 Oct 2026