VTS
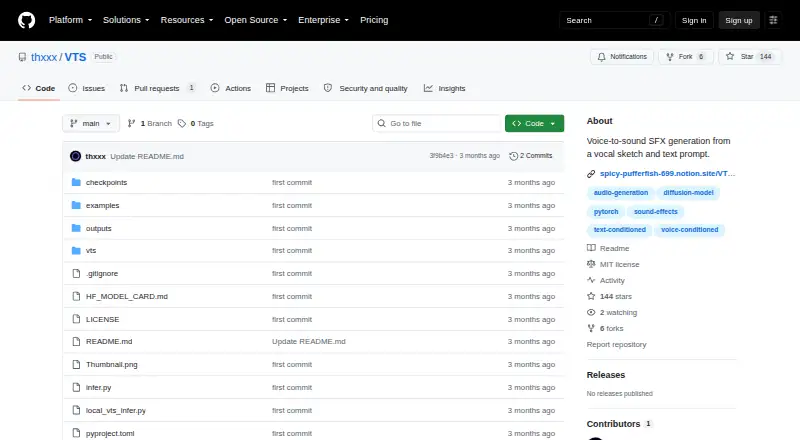
The facts below are what the maker publishes about VTS, checked and dated. Our editors have not written about it yet.
The facts
Each one read from VTS's own pages, with the date it was checked.
What it does
- API availability
- The model is not packaged as a Hugging Face Inference API pipeline and is not deployed by an Inference Provider.checked 4 Oct 2026
- Checkpoint
- The inference code uses the pretrained checkpoint named dynamic_v3_0415.ckpt, which is available from the linked Hugging Face model repository.checked 4 Oct 2026
- Checkpoint access
- If the Hugging Face repository requires authentication, inference setup uses an HF_TOKEN environment variable.checked 4 Oct 2026
- Deployment
- The repository provides an inference-only package with local model and runtime code; training code and datasets are excluded.checked 4 Oct 2026
- Generation
- Generated WAV files are written to a chosen output directory, and the default output duration follows the input audio duration unless a duration is specified.checked 4 Oct 2026
- Generation length
- Output duration defaults to the input audio duration, can be configured, and the checkpoint is tuned for short sound-effect clips.checked 4 Oct 2026
- Hardware
- The quick-start inference example specifies the CUDA device.checked 4 Oct 2026
- Hardware setup
- The documented local requirements pin PyTorch and torchaudio CUDA 12.4 builds, with instructions to install matching builds for other CUDA drivers.checked 4 Oct 2026
- How it works
- It uses voice conditioning derived from dynamic audio features alongside text conditioning from a prompt.checked 4 Oct 2026
- Integrations
- The inference code uses google/flan-t5-base as its text encoder and includes local vocoder code.checked 4 Oct 2026
- Intended users
- The checkpoint is intended for research and creative sound-effect generation from vocal sketches or short audio sketches plus text prompts.checked 4 Oct 2026
- License
- The project and model checkpoint are listed under the MIT License.checked 4 Oct 2026
- Limits
- The model is optimized for short sound-effect style clips, and output quality depends on the checkpoint, input audio, prompt text, and sampling settings.checked 4 Oct 2026
- Local inference
- The repository provides an inference-only package with local model and runtime code.checked 4 Oct 2026
- Output
- Generated audio files are written as WAV files to the chosen output directory.checked 4 Oct 2026
- Purpose
- VTS generates sound effects from a short vocal or audio sketch combined with a text prompt.checked 4 Oct 2026
- Sampling
- Sampling uses a local ODE solver and typically runs 64 steps with CFG scale 3.0.checked 4 Oct 2026
- Support
- The repository says to contact the maker at [email protected] with questions.checked 4 Oct 2026
- Text encoder
- The inference path encodes text prompts with google/flan-t5-base.checked 4 Oct 2026
- Training
- Training code and dataset manifests are not included in the inference package.checked 4 Oct 2026
- Voice conditioning
- Voice conditioning uses dynamic features derived from spectral centroid, RMS, and chroma-index signals.checked 4 Oct 2026
Alternatives to VTS
- 1
Resemble AI
Free planAndroidiOSWebAPI8.3From $280 a month - 2
ElevenLabs
Free planWebAPI7.6From $6 a month - 3
Morphic
Free planWeb7.4From $4 a month - 4
Sonilo
Free planAndroidiOSWebAPI7.4From $11.99 a month - 5
Creen
Free planAndroidiOSWeb7.3From $6 a month - 6
Mirelo
Free planWebAPImacOSWindows7.1From €20 a month