LiveBench
LiveBench is a free, open-source benchmark for evaluating large language models, designed to limit test contamination and use objective evaluation.
What LiveBench is
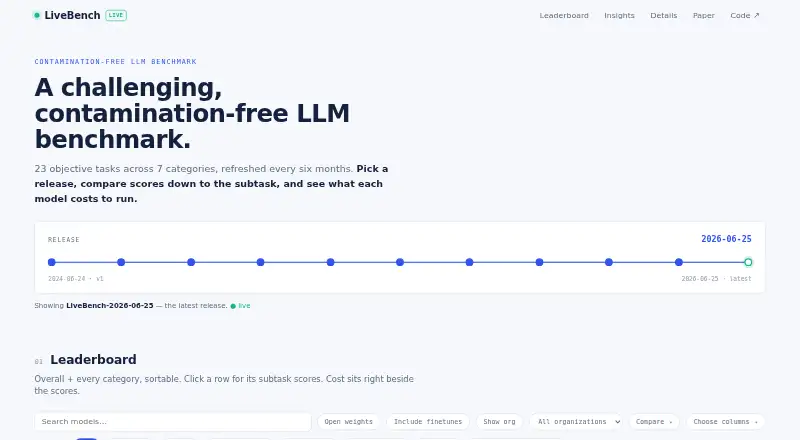
LiveBench is a free, open-source benchmark for evaluating large language models, designed to limit test contamination and use objective evaluation. Its current benchmark has 23 tasks across seven categories: Reasoning, Coding, Agentic Coding, Mathematics, Data Analysis, Language, and Instruction Following. The benchmark refreshes every six months. Its leaderboard presents overall and category scores, with model rows that expand to show subtasks. Insight views cover quality versus cost, ranked cost, and category profiles; the project defines cost per successful task as (Σ cost ÷ Σ questions ÷ score) × 100 for the selected scope. Questions have verifiable ground-truth answers and can be scored automatically without an LLM judge. To limit possible contamination, the project uses newly released questions and material based on recent datasets, papers, news, and movie synopses. The public project provides benchmark code and links to data on Hugging Face. Its documented Python command-line pipeline generates model answers, scores them, and displays results. It supports OpenAI-compatible endpoints and implemented inference for Anthropic, Cohere, Mistral, Together, and Google models.
Good
- Free and open source
- Seven categories with 23 objective tasks
- Scores can be evaluated without an LLM judge
- Leaderboard includes category and subtask scores
Watch out
- Benchmark refreshes every six months
- Local inference is unmaintained
- Agentic coding evaluations require Docker
- Task-specific images may take up to 150 GB
Who it suits
LiveBench suits people evaluating language models with objective tasks and category-level score views. Users who want to run evaluations can use its documented Python pipeline and supported API endpoints.
Verdict
LiveBench offers a regularly refreshed benchmark with objective scoring and cost-oriented insights. Running agentic coding evaluations involves Docker and substantial image storage, while local inference is unmaintained.
The facts
Each one read from LiveBench's own pages, with the date it was checked.
What it does
- Agentic coding requirements
- Evaluating agentic coding tasks requires Docker, and the README says task-specific images may require up to 150 GB of storage.checked 9 Oct 2026
- Benchmark scope
- The current site describes 23 objective tasks across 7 categories, refreshed every six months.checked 4 Oct 2026
- Categories
- The website lists Reasoning, Coding, Agentic Coding, Mathematics, Data Analysis, Language, and Instruction Following.checked 9 Oct 2026
- Contamination controls
- The repository README says questions draw on recently released datasets, papers, news articles, and IMDb movie synopses to limit potential contamination.checked 9 Oct 2026
- Current benchmark
- The website describes 23 objective tasks across 7 categories, refreshed every six months.checked 9 Oct 2026
- Insights
- The website provides quality-versus-cost, cost-ranked, and category-profile views.checked 9 Oct 2026
- Leaderboard
- The leaderboard lets visitors sort overall and category scores, inspect subtask scores, and compare cost per successful task.checked 9 Oct 2026
- Local inference
- The README describes local model inference as unmaintained and recommends serving models through an OpenAI-compatible API using vLLM.checked 9 Oct 2026
- Local models
- The README says local model inference is unmaintained and recommends serving models through an OpenAI-compatible API using vLLM.checked 4 Oct 2026
- Model compatibility
- The README says OpenAI-compatible API endpoints can be used and lists implemented inference support for Anthropic, Cohere, Mistral, Together, and Google models.checked 4 Oct 2026
- Model endpoints
- The repository documents custom OpenAI-compatible API endpoints and inference support for Anthropic, Cohere, Mistral, Together, and Google models.checked 9 Oct 2026
- Open source
- The project publishes its code in a public GitHub repository and links to benchmark data on Hugging Face.checked 4 Oct 2026
- Product
- LiveBench is described as a challenging, contamination-free LLM benchmark.checked 4 Oct 2026
- Purpose
- LiveBench is an LLM benchmark designed to limit test set contamination and use objective evaluation.checked 9 Oct 2026
- Run evaluations
- The repository provides a Python script that can generate model answers, score them, and show results; it supports selecting a model and benchmark subset.checked 9 Oct 2026
- Scoring
- The repository README says questions have verifiable objective ground-truth answers and are scored automatically without an LLM judge.checked 9 Oct 2026
- Support
- The repository invites model evaluation requests by GitHub issue or email at [email protected].checked 9 Oct 2026
Money
- Cost metric
- The site defines cost per successful task as (Σ cost ÷ Σ questions ÷ score) × 100 over the selected scope.checked 4 Oct 2026
Alternatives to LiveBench
- 1
DeepEval
Free planOpen sourceWebAPILinuxmacOS8.3From $200 a month - 2
Promptfoo
Free planOpen sourceWebAPILinuxmacOS7.8Free plan - 3
Braintrust
Free planWebAPISelf-hosted7.7From $249 a month - 4
Giskard
Free planOpen sourceWebAPILinuxSelf-hosted7.6Free plan - 5
TruLens
Free planOpen sourceAPISelf-hosted7.2Free plan - 6
Arena (formerly Chatbot Arena)
Free planOpen sourceWebAPISelf-hosted7.1Free plan