LibreCrawl
LibreCrawl is a free, MIT-licensed web crawler for technical SEO audits and website analysis.
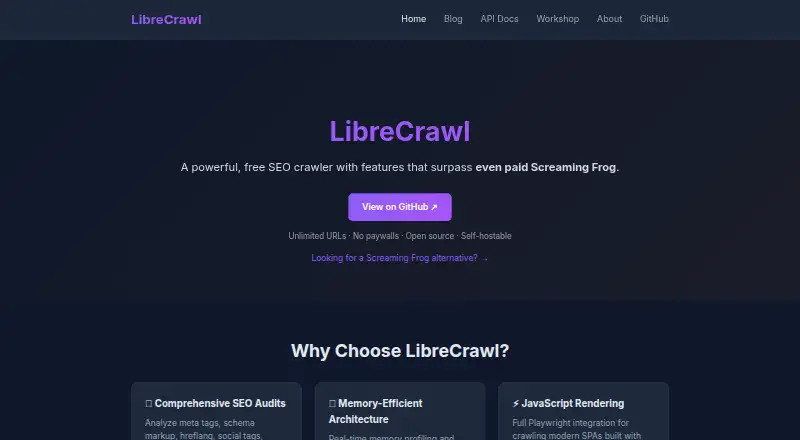
What LibreCrawl is
LibreCrawl is a free, MIT-licensed web crawler for technical SEO audits and website analysis. It checks meta tags, schema markup, hreflang, social tags, PageSpeed metrics, and other technical SEO issues. For JavaScript sites, it uses Playwright to render and crawl applications built with React, Vue, Angular, and Next.js, in either headed or headless mode. The maker says memory profiling and virtual scrolling support stable crawling of more than one million URLs. Results can be exported as CSV, JSON, or XML, with custom field selection and no stated export restrictions. LibreCrawl can be self-hosted, and its REST API provides endpoints for crawl control, settings, and exports. Every API endpoint requires session-based authentication; guest API users are limited to three crawls per 24 hours, tracked by IP address. The maker says it does not track users, collect analytics, or send crawl data back to itself, and encourages self-hosting for privacy. It supports web, Linux, macOS, and Windows use, with API access available. There are no paid tiers or subscriptions.
Good
- Audits technical SEO elements and PageSpeed metrics.
- Crawls JavaScript sites using Playwright.
- Exports crawl data as CSV, JSON, or XML.
- MIT-licensed, self-hostable, and has no paid tiers.
Watch out
- Guest API users are limited to three crawls per 24 hours.
- Every API endpoint requires session-based authentication.
- It does not provide keyword research, rank tracking, or backlink analysis.
Who it suits
LibreCrawl suits SEO consultants, agency developers, enterprise SEO teams, and open-source contributors who need technical site audits. Self-hosting is an option for users prioritizing control over crawl data.
Verdict
LibreCrawl focuses on technical SEO crawling, with JavaScript rendering, configurable exports, and self-hosting. Note the guest API cap and session requirement if you plan to use its API.
Plans and prices
From LibreCrawl's own pricing page, checked 7 Oct 2026.
| Plan | Price | What it gives you |
|---|---|---|
| LibreCrawl | Free | Unlimited URLs · no paid tiers · MIT license · Free and open source; no subscriptions. |
The facts
Each one read from LibreCrawl's own pages, with the date it was checked.
What it does
- API access
- Yeschecked 21 Sep 2026
- API authentication
- The REST API uses session-based authentication and requires a session for all endpoints.checked 7 Oct 2026
- Backlink analysis
- Nochecked 21 Sep 2026
- Competitor research
- Nochecked 21 Sep 2026
- Exports
- It exports crawl data as CSV, JSON, or XML, with custom field selection and no stated export restrictions.checked 7 Oct 2026
- Guest limit
- The API documentation states guest users are limited to three crawls per 24 hours, tracked by IP address.checked 7 Oct 2026
- Integrations
- The maker lists PageSpeed metrics and Playwright rendering; its API documentation describes REST endpoints for crawl control, settings, and exports.checked 7 Oct 2026
- Intended users
- The maker describes LibreCrawl for SEO consultants, agency developers, enterprise SEO teams, and open-source contributors.checked 7 Oct 2026
- JavaScript rendering
- It uses Playwright to crawl JavaScript sites, including React, Vue, Angular, and Next.js, in headed or headless mode.checked 7 Oct 2026
- Keyword research
- Nochecked 21 Sep 2026
- Open source
- LibreCrawl is MIT-licensed and can be self-hosted.checked 7 Oct 2026
- Purpose
- LibreCrawl is a web-based SEO crawler for website audits and analysis.checked 7 Oct 2026
- Rank tracking
- Nochecked 21 Sep 2026
- Scale
- The maker says its memory profiling and virtual scrolling support stable crawling of more than one million URLs.checked 7 Oct 2026
- Security and privacy
- The maker says LibreCrawl does not track users, collect analytics, or phone home with crawl data, and encourages self-hosting for privacy.checked 7 Oct 2026
- SEO audits
- It analyzes meta tags, schema markup, hreflang, social tags, PageSpeed metrics, and other technical SEO issues.checked 7 Oct 2026
- Site audit
- Yeschecked 21 Sep 2026
- Support
- The maker directs users to GitHub Issues for bug reports and feature requests, and GitHub Discussions for conversations.checked 7 Oct 2026
The company
- Founded
- 2025checked 28 Sep 2026
Money
- Free plan
- Yeschecked 21 Sep 2026
Where it runs
- Platforms
- The maker's repository describes Windows and Linux/Mac startup scripts and Docker installation; the application is accessed through a web browser.checked 7 Oct 2026
The full review of LibreCrawl
LibreCrawl is a technical SEO crawler for people who need to inspect websites, including JavaScript-rendered pages. It suits developers and SEO teams comfortable with self-hosting or API workflows; its clearest advantage is unlimited URL crawling at no cost, while the API’s guest cap and session requirement call for planning.
Overview
LibreCrawl concentrates on site audits rather than the broader work of SEO. It can surface technical issues and handle browser-rendered sites, but it does not cover keyword research, rank tracking, backlink analysis, or competitor research. Choose it for crawling and technical diagnosis, not as a single tool for an entire SEO program.
Key features
Audits examine meta tags, schema markup, hreflang, social tags, PageSpeed metrics, and other technical SEO issues. That scope is useful for teams investigating implementation and page-level health; readers who need competitive or search-performance research will need another product alongside it.
Playwright supports crawling sites built with React, Vue, Angular, and Next.js, in headed or headless mode. This is a meaningful advantage when pages depend on JavaScript to render their content. LibreCrawl’s maker says memory profiling and virtual scrolling support stable crawls exceeding one million URLs, a notable scale target for large sites.
Crawl results can be exported as CSV, JSON, or XML, and users can select fields without stated export restrictions. Its REST API provides crawl control, settings, and export endpoints. Every endpoint requires session-based authentication, so integrations must establish and manage a session rather than make unauthenticated calls. Guest API use is limited to three crawls per 24 hours, counted by IP address.
The MIT license allows self-hosting. The maker says the software does not track users, collect analytics, or send crawl data home, making self-hosting a relevant option for teams that want greater control over crawl data. Bug reports and feature requests go through GitHub Issues, while GitHub Discussions is the channel for conversation.
Pricing
LibreCrawl costs nothing, with no subscription. The free and open-source plan includes unlimited URLs and the MIT license, and there are no paid tiers. That removes a per-crawl or URL-quota tradeoff for routine crawling; the guest API limit still matters if you plan to automate without signing in. There is no free trial because the product is free.
Platforms
LibreCrawl is available on the web and through an API, and supports Linux, macOS, Windows, and self-hosted deployment. That combination gives teams desktop and hosted environments to work with, while self-hosting can suit privacy-conscious deployments.
Who it's for
SEO consultants, agency developers, enterprise SEO teams, and open-source contributors are the clearest audience. It is especially apt for teams auditing JavaScript-heavy sites, exporting crawl data into their own processes, or wanting an MIT-licensed crawler they can host themselves. It is a weaker fit for anyone seeking keyword, rank, backlink, or competitor research in the same application.
Pros and cons
- Pros: Unlimited URLs on a free MIT-licensed plan make large-scale crawling possible without a paid tier or subscription.
- Pros: Playwright rendering covers several common JavaScript frameworks, and exports include three formats with custom field selection.
- Pros: Self-hosting and the maker’s stated no-tracking, no-analytics approach appeal to users who want control over crawl data.
- Cons: The guest API is capped at three crawls per 24 hours per IP, and all API endpoints require a session.
- Cons: It omits keyword research, rank tracking, backlink analysis, and competitor research, so it cannot replace a broad SEO suite.
Alternatives
Open SEO Crawler is another free, MIT-licensed self-hosted option with unlimited URLs; choose it if avoiding accounts, API keys, and per-URL billing is the priority. Screaming Frog SEO Spider may suit users who prefer a freemium crawler with a 500-URL free crawl and an unlimited-URL paid licence.
WebCrawler Pro is worth considering if its free guest allowance of 50 requests per day or signed-in allowance of 100 requests per day better fits your request-based workflow. WebSite Auditor offers a 500-URL, one-project free plan with no paid report exports, and a free trial; it may fit users evaluating that project-based approach.
SpiderNow has a free plan limited to 10 single-page scans per month, with five scan-detail and issue views and five page metric scores; it is an alternative for small, bounded scanning needs. A1 Website Analyzer is a freemium option for macOS and Windows with a free mode that continues after a 30-day evaluation period. Beam Us Up is a free crawler with no limits stated. Crab is a free, open-source option for Linux, macOS, and Windows.
For broader category browsing, see SEO Crawler Software and SEO tools.
Verdict
Choose LibreCrawl if you need a focused technical crawler with JavaScript rendering, unlimited URLs, flexible exports, and the option to self-host without paying for a tier. Its main limitation is scope: it does not handle core research and tracking tasks, and API users must account for session authentication and the guest cap. For technical audits, it is a compelling free choice; for all-in-one SEO work, look elsewhere.
Getting started
- Visit the LibreCrawl website.
- Choose web use or a supported Linux, macOS, or Windows setup.
- For self-hosted use, use the MIT-licensed software.
- For REST API access, establish a session before calling endpoints.
Limits worth knowing
The product has no paid tiers or subscription. Guest API users are limited to three crawls per 24 hours, tracked by IP address.
Questions
How much does LibreCrawl cost?
LibreCrawl is free, with no subscriptions or paid tiers.
Is there a free plan or trial?
The listed plan is free. There is no free trial.
Which platforms does it support?
It supports web, Linux, macOS, Windows, API, and self-hosted use.
Is LibreCrawl open source?
Yes. It is MIT-licensed and can be self-hosted.
What does its API provide?
The REST API has endpoints for crawl control, settings, and exports. All endpoints require session-based authentication.
Who makes LibreCrawl?
The maker is LibreCrawl, founded in 2025.
Alternatives to LibreCrawl
- 1
WebCrawler Pro
Free planWebLinuxmacOSSelf-hosted7.9$1 usage-based - 2
Screaming Frog SEO Spider
Free planAPILinuxmacOSSelf-hosted7.8Free plan - 3
SpiderNow
Free planAndroidiOSWebAPI7.7From $6.99 a month - 4
Screaming Frog SEO Log File Analyser
Free planLinuxmacOSWindows7.6From $139 a year - 5
Crawlr
Free planWebAPI7.5From $8 a month - 6
Sitebulb
WebExtensionmacOSWindows7.5