EzAudio
EzAudio is a free, open-source diffusion model that generates audio from text prompts.
What EzAudio is
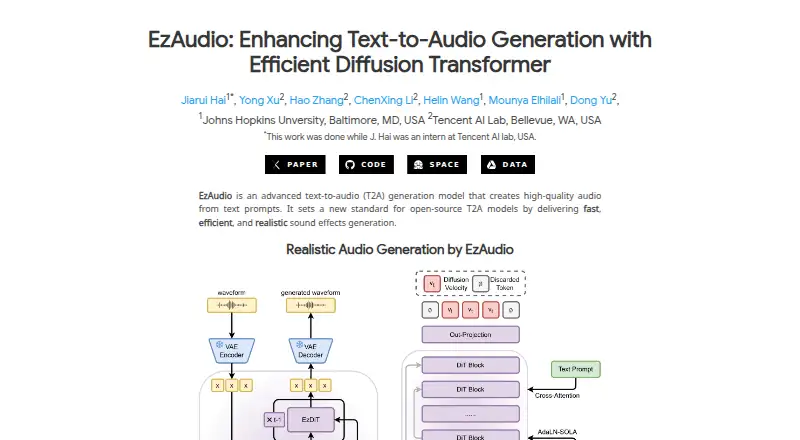
EzAudio is a free, open-source diffusion model that generates audio from text prompts. It also supports audio editing and inpainting, while its ControlNet example combines a text prompt with an audio reference. The model works in the latent space of a one-dimensional waveform variational autoencoder. Its paper describes an optimized diffusion transformer for convergence speed, training stability, and memory use, plus classifier-free guidance rescaling for stronger prompt alignment at higher guidance scores. Training uses unlabeled audio, machine-generated captions, and human-labeled fine-tuning data. Browser demos for EzAudio and EzAudio-ControlNet are linked, and code and checkpoints are available for local use. Example code uses PyTorch and SoundFile, with checkpoints hosted on Hugging Face. Local setup requires cloning the repository and installing Python dependencies; CUDA is selected when available, otherwise CPU. EzAudio is not deployed by an inference provider.
Good
- Generates audio from text prompts
- Supports editing and inpainting
- ControlNet accepts an audio reference
- Code and checkpoints support local use
- MIT-licensed GitHub repository
Watch out
- Not deployed by an inference provider
- Local installation requires Python dependencies
- Training pipeline and dataset remain listed as todo items
- Commercial use is unclear
Who it suits
It suits developers and creators who want open-source text-to-audio generation, editing, or inpainting. Users should be comfortable with browser demos or local Python setup.
Verdict
EzAudio provides text-to-audio generation alongside editing, inpainting, and reference-guided ControlNet examples. Its open-source code and browser demos offer access, but local use requires setup and the project lists some unreleased resources.
The facts
Each one read from EzAudio's own pages, with the date it was checked.
What it does
- Access
- The maker links to browser demos for EzAudio and EzAudio-ControlNet, and publishes code and model checkpoints for local use.checked 9 Oct 2026
- Audio editing
- The project describes text to audio generation, audio editing, and inpainting.checked 9 Oct 2026
- Authors and affiliations
- The project page lists Jiarui Hai and coauthors, affiliated with Johns Hopkins University and Tencent AI Lab.checked 9 Oct 2026
- Availability limitation
- The model page says EzAudio is not deployed by an inference provider.checked 9 Oct 2026
- ControlNet
- The repository includes a ControlNet demo and example code that generates audio using a text prompt and an audio reference.checked 9 Oct 2026
- Editing and inpainting
- The project describes support for audio editing and inpainting in addition to text-to-audio generation.checked 9 Oct 2026
- Efficiency
- The paper describes an optimized diffusion transformer designed to improve convergence speed, training stability, and memory usage.checked 9 Oct 2026
- Integrations
- The repository's example code uses PyTorch and SoundFile, and links to model checkpoints hosted on Hugging Face.checked 9 Oct 2026
- License
- The GitHub repository identifies its license as MIT.checked 9 Oct 2026
- Local requirements
- The usage example selects CUDA when available and otherwise uses CPU; installation requires cloning the repository and installing its Python dependencies.checked 9 Oct 2026
- Model design
- EzAudio uses an optimized diffusion transformer for audio latent representations and a one-dimensional waveform variational autoencoder.checked 9 Oct 2026
- Project page license
- The project website identifies its license as Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International.checked 9 Oct 2026
- Prompt alignment
- The model uses classifier free guidance rescaling to support stronger prompt alignment while preserving audio quality at higher guidance scores.checked 9 Oct 2026
- Prompt guidance
- The paper describes classifier-free guidance rescaling to improve prompt alignment while preserving audio quality at higher guidance scores.checked 9 Oct 2026
- Purpose
- EzAudio is a diffusion based model that generates audio from text prompts.checked 9 Oct 2026
- Release status
- The README lists automatic checkpoint downloading and release of the training pipeline and dataset as todo items.checked 9 Oct 2026
- Training
- The paper describes a three stage training approach using unlabeled audio, machine generated captions, and human labeled data for fine tuning.checked 9 Oct 2026
- Training resources
- The repository's todo list includes releasing the training pipeline and dataset.checked 9 Oct 2026
The company
- Founded
- 2024checked 28 Sep 2026
Where it runs
- Online demos
- The repository links to Hugging Face Spaces for EzAudio and EzAudio-ControlNet demos.checked 9 Oct 2026
Alternatives to EzAudio
- 1
Resemble AI
Free planAndroidiOSWebAPI8.3From $280 a month - 2
ElevenLabs
Free planWebAPI7.6From $6 a month - 3
Morphic
Free planWeb7.4From $4 a month - 4
Sonilo
Free planAndroidiOSWebAPI7.4From $11.99 a month - 5
Creen
Free planAndroidiOSWeb7.3From $6 a month - 6
Mirelo
Free planWebAPImacOSWindows7.1From €20 a month