EvalPlus
EvalPlus is a free, open-source framework for evaluating large language models on code-related tasks.
What EvalPlus is
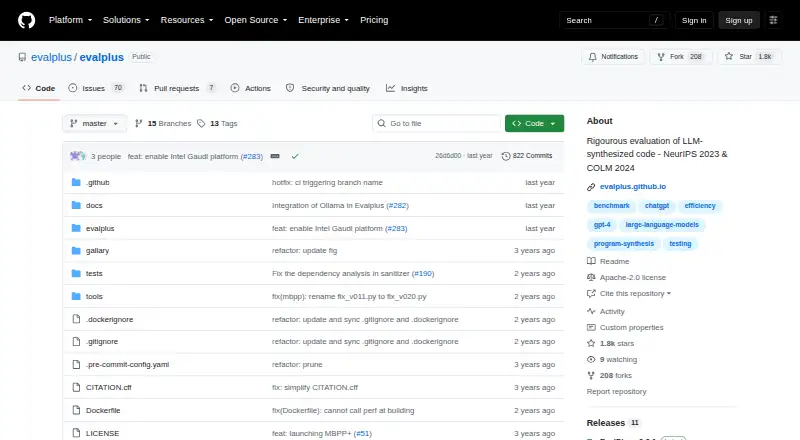
EvalPlus is a free, open-source framework for evaluating large language models on code-related tasks. It supports the HumanEval and MBPP benchmarks through expanded versions: HumanEval+ adds 80 times more tests than HumanEval, while MBPP+ adds 35 times more than MBPP. EvalPerf evaluates code efficiency with performance-exercising tasks and test inputs, and its evaluation is marked as *nix only. The project publishes leaderboards for HumanEval+, MBPP+, and EvalPerf results, and describes RepoQA as work on evaluators for long-context code understanding. Documented model backends include Hugging Face Transformers, vLLM, OpenAI-compatible servers, OpenAI, Anthropic, Google, Amazon Bedrock, Ollama, and Intel Gaudi. Installation uses pip, with optional vLLM and performance extras. Docker examples run evaluations in containers, described as safe code execution. EvalPlus is available through an API, on Linux, or self-hosted, under Apache License 2.0, with MIT compliance for files under evalplus/eval.
Good
- Expanded HumanEval+ and MBPP+ benchmarks
- EvalPerf measures code efficiency
- Leaderboards publish evaluation results
- Many documented model backends
- Docker-based execution is documented
Watch out
- EvalPerf is *nix only
- Requires technical installation
- No hosted commercial plan is listed
- License terms differ for eval files
Who it suits
EvalPlus suits model teams and developers evaluating LLM performance on programming tasks. It is useful for API, Linux, or self-hosted workflows that need benchmark and efficiency evaluations.
Verdict
EvalPlus provides benchmark, efficiency, and long-context evaluation components for code-focused language models. Its broad backend support and self-hosted options fit technical evaluation workflows, while EvalPerf has an operating-system limitation.
The facts
Each one read from EvalPlus's own pages, with the date it was checked.
What it does
- Benchmarks
- The framework supports HumanEval, MBPP, and EvalPerf evaluation.checked 11 Oct 2026
- Docker
- The README documents running code evaluation in Docker.checked 5 Oct 2026
- Efficiency evaluation
- EvalPerf evaluates the efficiency of LLM-generated code using performance-exercising tasks and test inputs.checked 11 Oct 2026
- EvalPerf leaderboard
- The EvalPlus site provides a leaderboard for EvalPerf code efficiency results.checked 5 Oct 2026
- Execution
- The README provides Docker-based examples for running code evaluation in a container.checked 11 Oct 2026
- HumanEval+
- HumanEval+ expands the original HumanEval tests by 80 times.checked 11 Oct 2026
- Installation
- EvalPlus can be installed from its GitHub repository or as a stable release using pip.checked 11 Oct 2026
- Intended audience
- The project is intended for evaluating LLM performance on code-related tasks.checked 5 Oct 2026
- Leaderboard
- The project links leaderboards for EvalPlus and EvalPerf benchmarks.checked 11 Oct 2026
- License
- The repository provides the software under the Apache License 2.0, with files under evalplus/eval additionally complying with the MIT License.checked 11 Oct 2026
- MBPP+
- MBPP+ expands the original MBPP tests by 35 times.checked 11 Oct 2026
- Model backends
- Documented backends include Hugging Face, vLLM, OpenAI-compatible servers, OpenAI, Anthropic, Google Gemini, Amazon Bedrock, Ollama, and Intel Gaudi.checked 11 Oct 2026
- Operating system limit
- The README labels EvalPerf as *nix only.checked 11 Oct 2026
- Purpose
- EvalPlus is a framework for rigorously evaluating large language models on code related tasks.checked 11 Oct 2026
- RepoQA
- The EvalPlus site describes RepoQA as work on evaluators for long-context code understanding.checked 11 Oct 2026
- Security
- The README describes Docker-based code execution as safe code execution.checked 5 Oct 2026
Where it runs
- Platform limit
- The README labels EvalPerf code efficiency evaluation as *nix only.checked 5 Oct 2026
The company
- Use by model teams
- The README says EvalPlus datasets have been used by teams including Meta Llama, Allen AI TÜLU, Qwen, DeepSeek, Snowflake, StarCoder2, Magicoder, and WizardCoder.checked 11 Oct 2026
Alternatives to EvalPlus
- 1
DeepEval
Free planOpen sourceWebAPILinuxmacOS8.3From $200 a month - 2
Promptfoo
Free planOpen sourceWebAPILinuxmacOS7.8Free plan - 3
Braintrust
Free planWebAPISelf-hosted7.7From $249 a month - 4
Giskard
Free planOpen sourceWebAPILinuxSelf-hosted7.6Free plan - 5
TruLens
Free planOpen sourceAPISelf-hosted7.2Free plan - 6
Arena (formerly Chatbot Arena)
Free planOpen sourceWebAPISelf-hosted7.1Free plan