Parler-TTS
Parler-TTS is a free, open-source text-to-speech model and Python library for generating speech from text prompts.
What Parler-TTS is
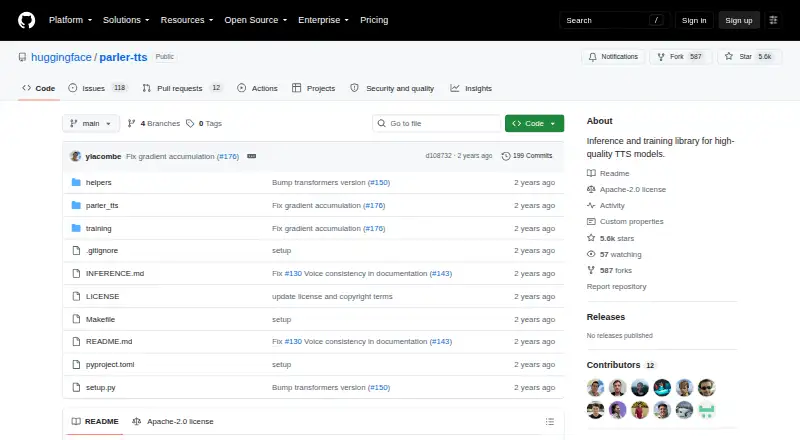
Parler-TTS is a free, open-source text-to-speech model and Python library for generating speech from text prompts. Prompts can guide characteristics such as gender, speaking rate, pitch, background noise and reverberation. The project offers Parler-TTS Mini with 880 million parameters and Parler-TTS Large with 2.3 billion parameters. Mini v1 was trained on 45,000 hours of audio, while the Mini v1 and Large v1 checkpoints use 34 named speakers to support consistent voice generation. The library installs from GitHub with pip and runs locally. Documentation covers Transformers usage, Google Colab and Kaggle notebooks, SDPA, Flash Attention 2, model compilation, batch generation and streaming. Training and fine-tuning guides are included. CUDA devices and Apple MPS are documented options, with an additional PyTorch command for Apple Silicon. Parler-TTS supports one language and WAV export. The repository and model cards identify Apache-2.0 licensing, and commercial use is permitted. Neither Mini v1 nor Large v1 is deployed by an Inference Provider.
Good
- Free and open source
- Commercial use permitted
- Prompt controls for multiple speech traits
- Supports local installation and self-hosting
- Includes training and fine-tuning guides
Watch out
- Supports one language
- Exports WAV format only
- Requires local device setup
- Models lack Inference Provider deployment
Who it suits
Parler-TTS suits developers who want a self-hosted, open-source speech generator with prompt-based voice controls and WAV output. It also fits users who can work with a single-language project and local Python installation.
Verdict
Parler-TTS provides self-hosted speech generation with detailed prompt controls, multiple model sizes and permissive licensing. Its one-language scope, WAV output and local deployment requirements should guide selection.
The facts
Each one read from Parler-TTS's own pages, with the date it was checked.
What it does
- Commercial use
- Yeschecked 20 Sep 2026
- Export formats
- WAVchecked 20 Sep 2026
- Inference features
- The inference guide documents SDPA and Flash Attention 2, model compilation, batch generation, and audio streaming.checked 8 Oct 2026
- Inference optimization
- The project describes support for SDPA, torch.compile, batching and streaming to improve inference speed.checked 9 Oct 2026
- Installation
- The library can be installed from the GitHub repository with pip and run locally using Python.checked 8 Oct 2026
- Integrations
- The model cards provide Transformers usage examples and links to Google Colab and Kaggle notebooks.checked 9 Oct 2026
- Languages
- 1checked 20 Sep 2026
- License
- The repository identifies its license as Apache-2.0, and the model card also lists Apache-2.0.checked 8 Oct 2026
- Local installation
- The library can be installed from the GitHub repository using pip.checked 9 Oct 2026
- Model license
- The Mini v1 and Large v1 model cards identify the license as Apache 2.0.checked 9 Oct 2026
- Model sizes
- The Mini v1 model has about 0.9 billion parameters and the Large v1 model has about 2 billion parameters.checked 9 Oct 2026
- Open source
- The project says its datasets, preprocessing, training code and model weights are publicly released under permissive licenses.checked 9 Oct 2026
- Prompt controls
- Text prompts can control speech characteristics including gender, speaking rate, pitch, background noise and reverberation.checked 9 Oct 2026
- Provider availability
- The Mini v1 and Large v1 model pages state that neither model is deployed by an Inference Provider.checked 9 Oct 2026
- Purpose
- Parler-TTS is a lightweight text-to-speech model that generates natural-sounding speech in a requested speaker style.checked 9 Oct 2026
- Related project
- The project is designed to accompany Data-Speech, a repository for speech dataset annotation.checked 8 Oct 2026
- Speaker choices
- The Mini v1 checkpoint was trained on 34 named speakers to support speaker consistency across generations.checked 8 Oct 2026
- Speaker consistency
- The Mini v1 and Large v1 checkpoints were trained on 34 named speakers for consistent voice generation.checked 9 Oct 2026
- Training
- The repository includes guides and code for training or fine-tuning a Parler-TTS model.checked 9 Oct 2026
- Training data
- The Mini v1 and Large v1 models were trained on 45,000 hours of audio data.checked 9 Oct 2026
- Voice controls
- Prompts can control characteristics such as gender, speaking rate, pitch, background noise, and reverberation.checked 8 Oct 2026
Where it runs
- Platform requirement
- The repository says Apple Silicon users need a nightly PyTorch build for bfloat16 support.checked 9 Oct 2026
- Platforms
- self_hostedchecked 20 Sep 2026
Alternatives to Parler-TTS
- 1
Resemble AI
Free planAndroidiOSWebAPI8.3From $280 a month - 2
Speechify
Free planAndroidiOSWebAPI8.3From $10 a month - 3
Algebras AI Game Localization Agent
Free planOpen sourceWebAPILinuxmacOS8.1From $15 a month - 4
Neocortex
Free planAndroidiOSWebAPI8.0From €9 a month - 5

Altered Studio
Free planWebAPImacOSSelf-hosted7.9From $30 a month - 6
Acapela Group
AndroidiOSWebAPI7.8From €99 a year