Crowl
Crowl is an open-source SEO crawler for collecting links, anchor text, and page content from websites.
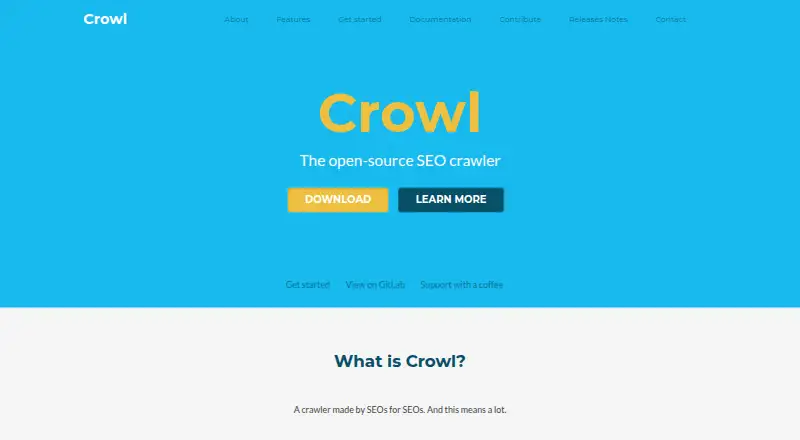
What Crowl is
Crowl is an open-source SEO crawler for collecting links, anchor text, and page content from websites. It runs on Windows, macOS, and Linux, with Linux and macOS described as the best fit because they are UNIX-like systems. Crawls support unlimited URLs by default, while the MAX_REQUESTS setting can impose a limit. Users can stop and resume a crawl, then export results to CSV or store them in MySQL. Project-specific INI files control request behavior, extraction, and output. Available settings include custom user agents, proxies, robots.txt compliance, delays, concurrency, HTTP basic authentication, exclusion patterns, rotating user agents, duplicate-link removal, and custom XPath extractors. Crowl can identify page language with a FastText model that must be downloaded separately. It is built with Python and Scrapy and is described as working best with Python 3.6 or later. GNU GPL v3 permits private or commercial use when modified or redistributed code remains under that license. The latest listed release is version 0.3.1 from July 27, 2021.
Good
- Unlimited URLs by default
- Stop and resume crawls
- CSV and MySQL output
- Custom XPath extraction
- Runs on Windows, macOS, and Linux
Watch out
- FastText language model requires separate download
- Latest listed release is from July 2021
- Provided without warranty
- Best fit is UNIX-like systems
Who it suits
Crowl is intended for SEO professionals who want a configurable crawler on Windows, macOS, or Linux. Its community contribution model may also suit users willing to participate in an open-source project.
Verdict
Crowl provides broad crawl controls, flexible extraction, and straightforward CSV or MySQL output without a paid plan. Its older listed release, separate language-model download, and no-warranty provision are important considerations.
The facts
Each one read from Crowl's own pages, with the date it was checked.
What it does
- Additional crawl features
- Release notes list exclusion patterns, proxies, rotating user-agents, HTTP authentication, request limits, duplicate-link removal and custom XPath extractors among Crowl features.checked 9 Oct 2026
- Authentication
- Crowl supports HTTP basic authentication settings for crawling environments that require a username and password.checked 9 Oct 2026
- Crawl control
- Crowl can stop and resume crawls.checked 9 Oct 2026
- Crawl controls
- Crowl supports stopping and resuming crawls and allows a custom user-agent.checked 9 Oct 2026
- Crawl data
- Crowl extracts links and anchor texts, and can extract page content.checked 9 Oct 2026
- Customization
- Crowl settings are configured in project-specific INI files, with options for request behavior, extraction, and output.checked 9 Oct 2026
- Exports
- Crowl provides CSV export by default and supports storing crawl data in MySQL.checked 9 Oct 2026
- Exports and storage
- The maker lists CSV export and MySQL storage as built-in output options.checked 9 Oct 2026
- Integrations
- The documentation describes CSV files and MySQL as output options; it does not state integrations with third-party SEO services.checked 9 Oct 2026
- Intended users
- The maker describes Crowl as designed for SEO professionals and invites contributors to join its volunteer community.checked 9 Oct 2026
- Language detection
- Crowl can identify the language of crawled page content using a FastText model, which must be downloaded separately.checked 9 Oct 2026
- License
- Crowl is distributed under GNU GPL v3, which allows private or commercial use provided modified or redistributed code is shared under the same license.checked 9 Oct 2026
- Maintenance
- The release notes list version 0.3.1 dated July 27, 2021, as the latest release shown there.checked 9 Oct 2026
- Product
- Crowl is an open-source SEO crawler made by SEOs for SEOs.checked 9 Oct 2026
- Request settings
- Configuration includes custom user agents, optional proxies, robots.txt compliance, request delays, and concurrent request settings.checked 9 Oct 2026
- Support
- The maker provides a contact form for questions and suggestions and links to Buy Me a Coffee for voluntary project support.checked 9 Oct 2026
- Support and community
- The project invites community contributions, provides a contact form, and links to optional supporter funding.checked 9 Oct 2026
- Technology
- Crowl is developed using Python and Scrapy, and the maker says it works best with Python 3.6 or later.checked 9 Oct 2026
- URL limit
- The feature list says Crowl supports unlimited URLs; configuration also offers MAX_REQUESTS, defaulting to 0 for no limit.checked 9 Oct 2026
- Warranty
- The product page states that Crowl is provided without warranty.checked 9 Oct 2026
Money
- Free plan
- Yeschecked 21 Sep 2026
Where it runs
- Platform
- Crowl works with Windows, Mac OS, and Linux; its installation guide says it works best on UNIX-like systems, including Linux and macOS.checked 9 Oct 2026
- Platforms
- The maker says Crowl works with Windows, Mac OS and Linux.checked 9 Oct 2026
Alternatives to Crowl
- 1
WebCrawler Pro
Free planWebLinuxmacOSSelf-hosted7.9$1 usage-based - 2
Screaming Frog SEO Spider
Free planAPILinuxmacOSSelf-hosted7.8Free plan - 3
SpiderNow
Free planAndroidiOSWebAPI7.7From $6.99 a month - 4
Screaming Frog SEO Log File Analyser
Free planLinuxmacOSWindows7.6From $139 a year - 5
Crawlr
Free planWebAPI7.5From $8 a month - 6
Sitebulb
WebExtensionmacOSWindows7.5