
CrawlObserver
CrawlObserver is a free private-beta SEO crawler available through the web and an API.
What CrawlObserver is
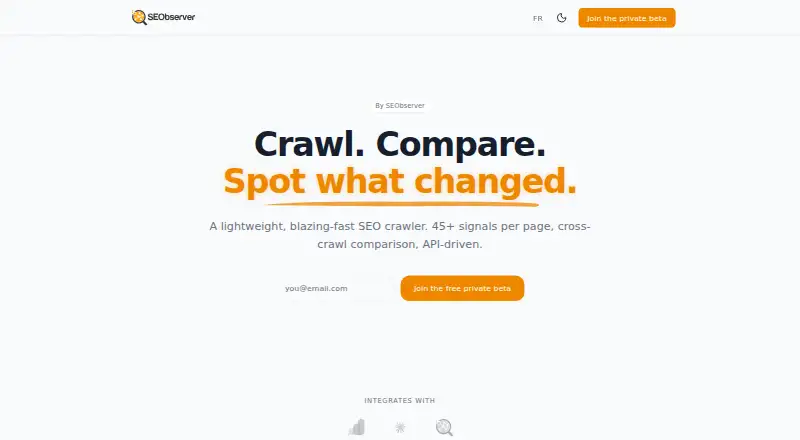
CrawlObserver is a free private-beta SEO crawler available through the web and an API. It reports more than 45 signals per page and describes audits without a page ceiling, including sites with 500K+ pages. Crawl comparisons show added or removed URLs and changes to redirects, titles, and canonicals. Technical checks cover redirect chains, internal PageRank, SimHash duplicate detection, and broken internal or external links. Internal authority-flow views help identify orphan pages, linking opportunities, and pages concentrating too many links. JavaScript rendering can be off, automatic, or always enabled, with automatic detection for React, Vue, Next.js, and Nuxt. Its REST API launches crawls and retrieves results. CrawlObserver says it respects robots.txt, crawl-delay, and per-host politeness delays, and uses post-DNS validation to block private IP ranges. Results are stored in ClickHouse.
Good
- 45+ signals per page
- No stated page ceiling
- Crawl comparison tools
- REST API access
- Optional JavaScript rendering
Watch out
- Private beta availability
- No public release date stated
- Keyword research unavailable
- Rank tracking unavailable
Who it suits
It suits technical SEO audits, monthly tracking, internal-link analysis, migration checks, broken-link work, and client reporting. The service is currently presented as a free private beta.
Verdict
CrawlObserver combines large-scale crawling, technical checks, comparisons, internal-link analysis, and API control. Its private-beta status and lack of keyword research or rank tracking define its current scope.
Plans and prices
From CrawlObserver's own pricing page, checked 12 Oct 2026.
| Plan | Price | What it gives you |
|---|---|---|
| Free private beta | Free | Private beta access; no page ceiling stated |
The facts
Each one read from CrawlObserver's own pages, with the date it was checked.
What it does
- API
- The product offers a REST API to launch crawls, fetch results, and integrate audits into workflows.checked 12 Oct 2026
- API access
- Yeschecked 23 Sep 2026
- Audience
- The stated use cases include technical SEO audits, monthly tracking, client reporting, internal-link analysis, and site-owner migration checks.checked 12 Oct 2026
- Audits
- The site says audits have no page ceiling and can be used on sites with 500K+ pages.checked 12 Oct 2026
- Authority data
- Connecting a SEObserver account enables crawl cross-referencing with Majestic metrics including TrustFlow, CitationFlow, backlinks, referring domains, and Topical TrustFlow.checked 12 Oct 2026
- Availability
- The site invites users to join a free private beta; it does not state a public release date or pricing plan on the page.checked 12 Oct 2026
- Backlink analysis
- Yeschecked 23 Sep 2026
- Broken links
- It detects broken internal and external links, expired domains, and hotlinks to third-party resources.checked 12 Oct 2026
- Comparison
- It compares crawls to show added or removed URLs and changes to redirects, titles, and canonicals.checked 12 Oct 2026
- Crawl comparison
- It compares crawls to show added or removed URLs and changes to redirects, titles, or canonicals.checked 12 Oct 2026
- Crawl limits
- The site describes audits as unlimited, with no page ceiling, including for sites with 500K+ pages.checked 12 Oct 2026
- Data storage
- Crawl results are stored in ClickHouse, described as a columnar database.checked 12 Oct 2026
- Integrations
- The page lists Google Search Console, Claude Code, and SEObserver under “Integrates with.”checked 12 Oct 2026
- Intended users
- The page presents use cases for technical SEO audits, monthly tracking, internal linking analysis, broken-link detection, and client reporting.checked 12 Oct 2026
- Internal links
- It visualizes internal authority flow and helps identify orphan pages, linking opportunities, and pages concentrating too many links.checked 12 Oct 2026
- JavaScript rendering
- Rendering can be turned off, set to automatic, or always enabled; automatic mode detects frameworks including React, Vue, Next.js, and Nuxt.checked 12 Oct 2026
- Keyword research
- Nochecked 23 Sep 2026
- Performance
- The site reports about 170 MB of memory per crawl, real-time results, and 10+ concurrent crawls.checked 12 Oct 2026
- Product
- CrawlObserver is a lightweight SEO crawler with 45+ signals per page, cross-crawl comparison, and API control.checked 12 Oct 2026
- Rank tracking
- Nochecked 23 Sep 2026
- Rendering
- JavaScript rendering can be set to off, automatic, or always; automatic mode detects frameworks including React, Vue, Next.js, and Nuxt.checked 12 Oct 2026
- REST API
- The full REST API can launch crawls and retrieve results for workflow automation.checked 12 Oct 2026
The company
- Data ownership
- The site describes CrawlObserver as open source and says users' data belongs to them.checked 12 Oct 2026
Money
- Free plan
- Yeschecked 23 Sep 2026
Alternatives to CrawlObserver
- 1
WebCrawler Pro
Free planWebLinuxmacOSSelf-hosted7.9$1 usage-based - 2
Screaming Frog SEO Spider
Free planAPILinuxmacOSSelf-hosted7.8Free plan - 3
SpiderNow
Free planAndroidiOSWebAPI7.7From $6.99 a month - 4
Screaming Frog SEO Log File Analyser
Free planLinuxmacOSWindows7.6From $139 a year - 5
Crawlr
Free planWebAPI7.5From $8 a month - 6
Sitebulb
WebExtensionmacOSWindows7.5